
DeepSeek发布全新Agent架构
DeepSeek公布下一代agent harness理念
Is it okay to share my experiments implementing research papers on my own LLM here? [P]
Hey everyone!
I've built and trained a small LLM (~8M parameters) from scratch using PyTorch, mainly as an experimental lab where I can implement and test ideas from different research papers.
I've been documenting the whole journey through casual blogs, including my mistakes, experiments, and things I've learned.
So far:
Next up is KV caching, followed by PagedAttention, Orca, and whatever else I find interesting.
Just wanted to ask if sharing these experiments and blogs here would be welcome. Nothing promotional, just me experimenting, learning, and hopefully getting feedback from people who know more than I do.
[link] [comments]

I built a scikit-learn for RSI [P]
 | After reading a bunch of RSI papers, I keep coming back to familiar problems from RL and evolutionary search:
That motivated us to build Gear, an open-source, meta-learning-inspired framework. A task agent produces execution traces; a meta-agent uses those traces and evaluation feedback to improve prompts, tools, workflows, and context management. Gear separates search decisions from execution and evaluation. Our goal is a scikit-learn for RSI, making approaches such as GEPA, RRSI, and Harness² easier to implement and compare. We currently have a working GEPA variant with shared failure diagnosis and staged evaluation. With GPT 5.6 Luna held at medium reasoning effort, we observed these task pass rates:
At max effort on Marketing, Luna with the optimized harness reached 88.88% objective completion, versus 84.08% for Astra + Codex. Strict task pass rates were 53% versus 57%, so the advantage was in partial completion. Separately, with both models using the same optimized DSH at max effort, Luna’s estimated API cost averaged $0.0568 per task versus $1.1858 for Astra—95.21% lower, excluding optimization and infrastructure costs. We’d welcome feedback on candidate evaluation and diversity preservation under limited budgets. [link] [comments] | |||||||||||||||
telemetry.dev
LLM observability for AI agents
Coding Wrapped
See how you really vibe code with Claude Code & Codex
AC Bridge
Your smart lights show when Claude Code or Codex needs you.
ChatGPT and Codex usage limits merging
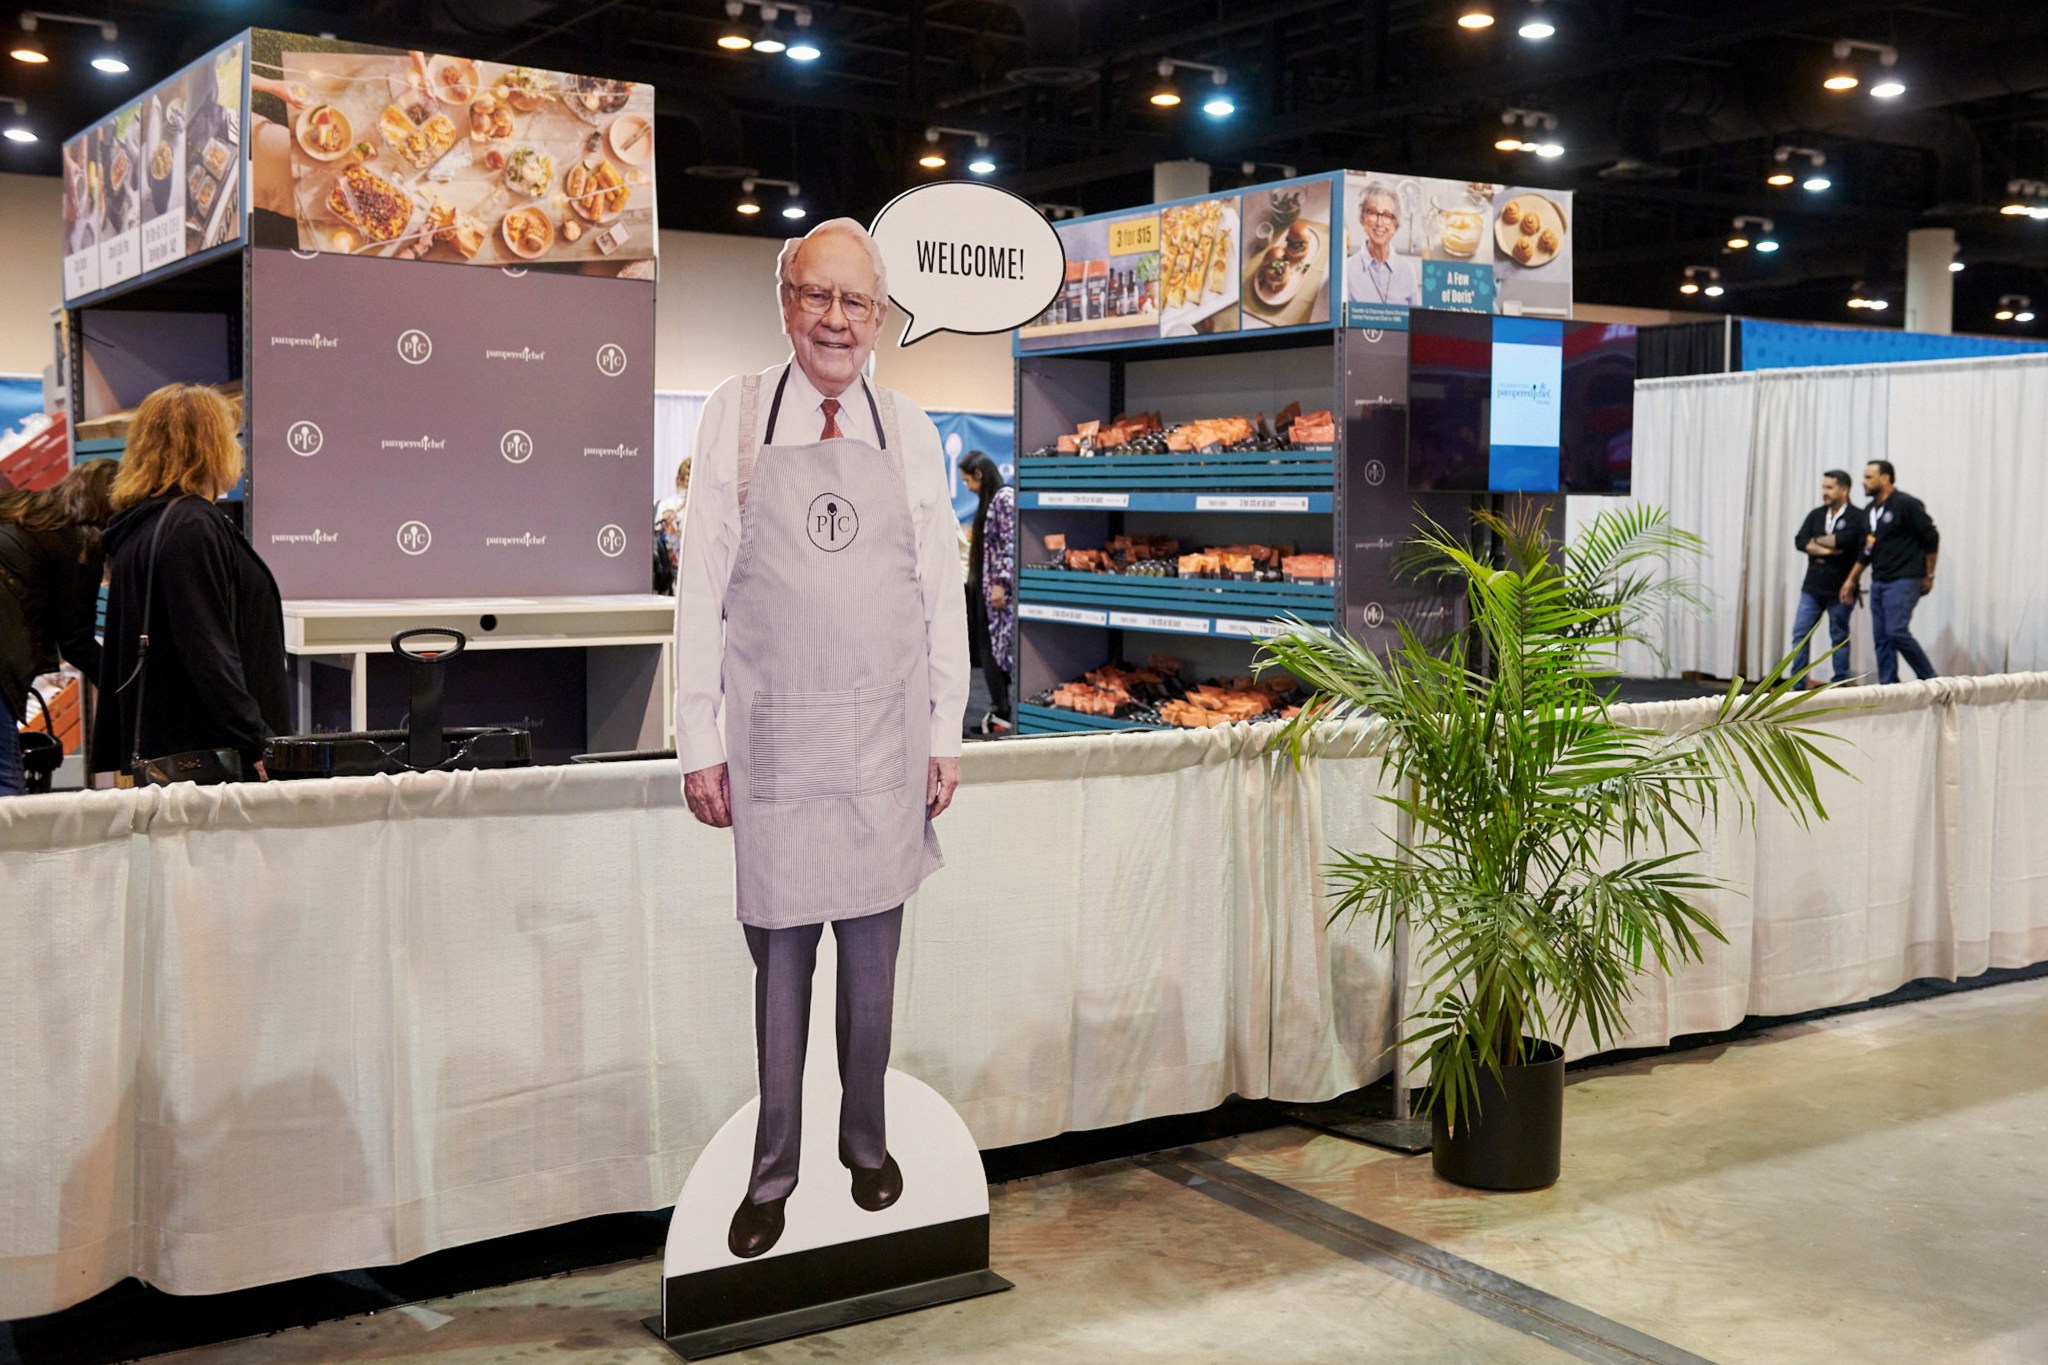
Tech stocks just lost more than $1 trillion in a day—a gothic horror test for the ‘moats’ Warren Buffett taught Wall Street to love
Markets are ushering in a particularly gothic Halloween as the AI trade exposes a crumbling aristocratic pile of early 21st century capitalism. Wall Street has been describing itself in castle-adjacent terms for years.
Jamie Dimon has long talked to JPMorgan shareholders about the bank’s “fortress balance sheet.” His 2015 letter set aside a section to answer the question of what the phrase even meant. By 2021, he’d added a second castle word, warning that “the moats that protect this company are not particularly deep.”
The moat came from Warren Buffett. In a 1999 Fortune article with Carol Loomis, he argued that the key to investing is a company’s competitive advantage and how durable it is, and that the businesses worth owning have wide moats around them.
The gothic novel’s favorite picture of danger is a castle falling apart, and for about 250 years the two have traded images: the castle and the moat, the vampire, the creature built in a lab. This Halloween season has them rushing to the front of the conversation, with a two-day rout in tech stocks on Thursday and Friday turning on whether the AI giants’ moats will hold, as gothic horror booms on bookshelves and movie screens.
Horror took 15.5% of the domestic box office in 2025, according to The Numbers, and U.S. horror book sales rose 7% through the first nine months of 2025, per Circana BookScan, while adult fiction overall grew just 1%. The New York Times asked Friday why every book is gothic now, with publishers putting the label on everything from family sagas to space operas, and several film critics commenting that Nathan Fielder’s smash-hit business-scandal documentaryYou Can See Everything is a twisted, even gothic romance in the tradition of Alfred Hitchcock.
The moats get tested
The selling started with Alphabet. The stock fell 12.6% Thursday, wiping out roughly half a trillion dollars in market value, after the Google parent’s quarterly report. Revenue from the core search unit fell short, partly because of the popularity of less-profitable “AI mode” searches and the company burning cash faster than expected. Its free cash flow came in at negative $9.1 billion, against the negative $2.23 billion analysts expected, per FactSet.
The S&P 500’s worst performer was software giant ServiceNow, which dropped 27% the same day on slowing revenue growth and disappointing guidance. By Friday morning, it was Amazon’s and Intel’s turn, with Intel down roughly 25% before the opening bell. Big Tech lost nearly $900 billion in market value after another sharp rise in AI spending in the third quarter, the Financial Times calculated. Nasdaq 100 companies lost more than $1 trillion in market value Friday alone. Reddit, whose shares fell more than 22% premarket Friday, is pulling up the drawbridge: it’s moving to a logged-in experience as AI eats search.
The irony is spooking investors. AI is eating into the businesses that throw off the cash, and the cash is going into AI anyway. The hyperscalers have raised $326 billion in stock and bonds this year to pay for the build-out, more than triple 2025, according to S&P Global Market Intelligence data.
The question underneath it is the one Apollo chief economist Torsten Slok put to clients the morning Alphabet fell. “With AI disruption potentially around the corner, there is a lot of discussion about moats at the moment,” he wrote in his Daily Spark note Thursday.
He built on finance professor Aswath Damodaran, the “dean of valuation,” who compiled a list of sources of competitive advantage, including brand strength, switching costs, network effects, cost advantages and legal protection. Then he boiled it down to an AI moat checklist of three questions: does the company own data its rivals can’t get, is its product part of how customers do their jobs every day, and can it charge more without customers walking away?
Judging by that third test, the companies selling AI don’t seem to measure up. OpenAI’s new GPT-6.1 Terra model costs up to half as much per token as the version before it. An index from expense-management firm Ramp, which looked at what companies actually pay Anthropic and OpenAI, shows token prices down roughly 35% since the end of June, in what Axios called a price war.
The companies paying for AI aren’t getting much back yet, either. In an Oct. 24 note, Slok sent a tremor through Wall Street terminals with an argument that AI “has delivered zero financial payoff to corporate America outside of tech.” Revenue per worker and profit margins are rising for the Magnificent Seven and flat for the rest of the S&P 500, he noted, and mainstream companies are starting to treat token spending as a cost center that weighs on margins rather than a source of growth.
The first castle was a fake
Xavier Aldana Reyes, a researcher at the Manchester Centre for Gothic Studies, told the Times that interest in the gothic tends to surge during periods of social anxiety and political turmoil. Literary agent Mary C. Moore put the genre’s subject more bluntly, telling the paper that “Gothics are all about exposing what is rotten at the core of something shiny/wealthy.”
The genre was invented by a scion of wealth who knew the old order from inside and drew a salary without working at all. Horace Walpole was the son of UK Prime Minister Robert Walpole, and hisThe Castle of Otranto, published in 1764, is generally regarded as the first gothic novel.
He passed it off as a translation of an obscure Italian work, found in the library of an old Catholic family in northern Eng
Against SURA
The AI Futures Project[1] distinguishes several different plans for navigating the AI transition, which I'll lump into two broader categories:
Plan A (my combination of their Plan A/S/Other) involves working for a global pause on AI development, hopefully lasting decades. During this pause, we either research preparatory technologies like alignment or human intelligence amplification, or take actions to "fortify" the pause so that it can last indefinitely.
Plan C (my combination of their Plan B/C+/C/sort of D)[2] is for a world where we fail at getting a global pause, and race dynamics continue to dominate. If the leading AI companies are alignment-pilled, they coordinate a mutual pause among themselves, lasting the length of their joint lead over the leading non-alignment-pilled AI company. Then they "burn the lead" researching alignment, and release hopefully-aligned superintelligence at the last possible moment before the racing non-alignment-pilled AI companies beat them. The exact calculus changes depending on who is in the lead when - is there one alignment-pilled AI company with a six-month lead in front of everyone else? Are there two alignment-pilled AI companies with a joint two-month lead in front of their nearest competitor? Etc. The point is, if it's impossible to stop the race, that six-month or two-month lead is the amount of time they have to prepare, and they can spend it more or less wisely.[3] The point of burning their lead at the last moment is that they can do alignment research with very advanced, right-on-the-brink-of-superintelligence AIs. This is a dangerous plan, and there would be many subtle points they would have to get right, but in a world where nobody can get a global pause in time, it's hard to think of a better one.
Plan A benefits from raising mass awareness, educating politicians, and preparing the verification technology that could enforce a pause treaty. Plan C benefits from alignment-pilling companies, having the alignment-pilled companies be as far in the lead as possible, making sure the alignment-pilled companies will burn their lead when the time comes, and giving them as good alignment teams as possible (so that burning the lead produces good results).
From the beginning of AI safety as a community to about 2023, the conventional wisdom was that our chances of Plan A were slim, and we should be preparing for Plan C. From about 2023 onward, as the general population woke up to the implications of ChatGPT, we rightly concluded that the chance of getting Plan A was better than expected, and we should invest more resources into trying to make it work. During both periods, the natural strategy was to work as hard as we can to get Plan A, where chances of survival are highest, but to be prepared to execute Plan C competently as a backup if that didn't pan out.
Now I think the pendulum has swung too far. New members of the community are unaware that Plan C was ever considered a possibility, or think it's some kind of accelerationist plot to distract us from Plan A. Older members heap scorn on it and act like everybody knows it's been debunked. Most concerningly, people propose burning our chances of executing Plan C in exchange for infinitesimal increased chances of getting Plan A, or even for no increased chance of Plan A at all.
I'll lump these ideas together under the heading of "SURA" - the idea that the only ethical course is for people/companies/countries to Stop Unilaterally + Raise Awareness, with no plan for what happens if race dynamics continue anyway. I interpret the planks of SURA's platform as:
- Individual alignment-pilled AI companies are morally obligated to stop unilaterally, regardless of whether they expect race dynamics to continue in their absence.
- Individual alignment-pilled employees at these companies should quit, regardless of whether they're in capabilities or alignment roles, and regardless of whether they think their company is morally better than its competitors.
- Individual alignment-pilled countries (for example, a hypothetical future alignment-pilled US) should ban or heavily restrict AI progress unilaterally, regardless of whether they expect other countries (for example, China) to continue racing in their absence.
All of these planks are net negative in a world where we end up needing Plan C:
- If we demand that leading alignment-pilled companies quit the race unilaterally, then we ensure that non-alignment-pilled companies end up in the lead.
- If we demand that alignment-pilled company employees quit their jobs, this makes companies less alignment-pilled and less prepared to research alignment if they need to. It also is likely to decrease the lead that alignment-pilled companies have over the nearest non-alignment pilled company.
- If we demand that the US cease AI research unilaterally (ie without a mutual pause treaty with China), we ensure either that China gets superintelligence first, [4]or that the US has to restart with zero lead when it realizes its mistakes.
SURA's continuing popularity despite these downsides comes from a set of questionable assumptions:
- Alignment is doomed (without some extraordinary extra advantage like decades of time, or superhuman geniuses). Therefore, Plan C is also doomed - or, at best, it raises our chances of survival from something like 0.00001% to something like 0.00002%. Therefore, there is no reason to optimize for Plan C.
- Racing to build superhuman AI is deontologically evil, and it's prohibited for good people to do it regardless of whether or not it may have good consequences.
- Racing burns timeline, so anyone unilaterally quitting the race would give us more timeline, which we could use for good things.
- If lots of people quit, that will raise awareness, which could be helpful for getting a global pause.
Conclusions of my DIY Inkhaven
Epistemic status: describing my own experiment results.
AI use: review, research (stats), fact-checking, grammar & light phrasing.
I applied to the next Inkhaven cohort and was rejected. This was surprising and very unfortunate. While writing my application and answering why they should accept me, I felt like I'd one-shotted myself into writing. My goals were:
- Run an experiment to verify my hypothesis that I couldn't write well. I also implicitly assumed that I didn't have anything useful to say or to add, so no one would read what I write anyway.
- I wanted to get better at thinking, and to me writing is a better form of thinking.
- I wanted to use language more eloquently even outside of writing.
- Writing is meditative and deep work, so I wanted to become more productive by writing more.
I was sad to be rejected, and I still don't know why. Fortunately, I have my agency, so I just decided to do my own Inkhaven instead. Obviously, I wouldn't stay at Lighthaven with a bunch of other people or receive guidance from people like Scott Alexander and Aella. Also, all of this is happening as part of my normal life, and I have other stuff to do as well.
In reality, I started writing even before I submitted my application, because I needed samples of my writing and I wanted to check whether I actually enjoyed doing it. After submitting my application, it felt cool to just write until the start of the cohort. I could compare about 30 days of writing on my own with a month at the cohort with guidance. Also, I would have more writing to compare before and after. After the rejection, there was a temptation to just give up, but I decided to continue.
Including this post on October 31, my totals are:
- 21 posts on LessWrong: about 19,000 words and 109,000 characters.
- Around a dozen posts on my private blog: roughly 6,000 words and 30,000 characters.
The earlier 20 LessWrong posts have 740 karma across 441 votes and 95 comments as of October 31. These word and character counts exclude footnotes; characters include spaces. One additional LessWrong submission was automatically rejected after an LLM detector flagged it.
I started by writing on LessWrong about stuff I found interesting. I would just get some random idea that I found interesting enough to explore. I did try to optimize for more karma.
Writing 500 words for LW, assuming you want other people to like it, felt quite hard. I could obviously bumble on for 500 words pretty easily and just publish that. I still had to relax my requirements a bit - for example, I never checked whether someone had written on the topic before. I knew that if I did, I would feel like I had nothing to add, so I just wrote, ignoring the fact that this could be a duplicate.
My first hit was "A fascinating case of an LLM prompt-injecting its own user". I saw this a long time ago and was extremely impressed and fascinated. Originally I assumed that everyone had seen it too. Apparently, something didn't have to be new to me to be useful to someone else. But since I had to write something, I decided to write about this. This was fairly early in the process (day 5, October 6) and definitely helped me feel less like "everyone else is so cool, you have nothing to add or say, and no one will read whatever you write."
My post with the most karma is "Quantity vs quality in pottery is a lie", which as of now has 176 karma. I literally read that anecdote in a book. I feel like, since I was looking for ideas to write about, I got curious about their experimental setup. To my surprise, it wasn't a scientific study, but an anecdote about a photography class that had been rewritten as pottery. My conclusion from this was that people at LessWrong like becoming less wrong. But this is a hard niche to reliably produce content in.
Two other highly upvoted posts are "Gluten-free water" and "I can't believe it's not BUTTER!".
In both cases, I noticed something peculiar in my life, dug deeper into it, and found more examples of similar things.
My "worst" post was "When bureaucracy gives you something it shouldn't". To be honest, I was writing it late in the day in a hurry just to get something out. Originally, it was downvoted below my personal strong upvote, but with time it got to +1 above my own strong upvote. I have no clue why.
I didn't engage in the comments much, since it didn't count toward my original proxy goal of publishing 500 words a day.
At some point, I started running out of steam, and overall it felt cumbersome. Writing for LW is quite hard. I applied high standards, and it took time. Eventually I switched to my private blog, where I would cover more personal topics and the posts didn't have to be as rigorous.
This made it easier and more fun. I mostly wrote my opinions or stories from my life, and it was easy and pleasant to write. This didn't feel like work and was enjoyable. I suspect these topics are just closer to my heart than the topics I would be writing about on LW (but I now catch myself realizing that I actually have no clue whether that's true - perhaps my personal reflections would be enjoyed on LW too). I feel like I will likely continue writing on my private blog (e.g., I now often catch myself thinking that this situation or feeling is interesting and I want to write about it to preserve it or to signal to others) and on LW very occasionally when there is something really burning inside me that I want to write about.
In terms of my original goals
Run an experiment to verify my hypothesis that I couldn't write well.
"Well" is unclear. I've got 176 karma on a post, and my posts have around 700 karma between the