
Is it okay to share my experiments implementing research papers on my own LLM here? [P]
Hey everyone!
I've built and trained a small LLM (~8M parameters) from scratch using PyTorch, mainly as an experimental lab where I can implement and test ideas from different research papers.
I've been documenting the whole journey through casual blogs, including my mistakes, experiments, and things I've learned.
So far:
Next up is KV caching, followed by PagedAttention, Orca, and whatever else I find interesting.
Just wanted to ask if sharing these experiments and blogs here would be welcome. Nothing promotional, just me experimenting, learning, and hopefully getting feedback from people who know more than I do.
[link] [comments]
Surviving "The Graduate"
Generalized belief states in transformers
Many thanks to Xavier Poncini, Paul Riechers, Fernando Rosas, and Matt Smith for useful conversations.
1. Introduction
Despite the recent successes of transformers and other sequence models, there are still many open questions about their basic principles of operation. For example, what internal representations do these models use for prediction and generation? Can we decode, interpret, and manipulate such representations? Is it even possible to consider a notion of representation without reference to an external world model?
To make progress on these questions, I propose a general way to define, decode and manipulate representations in sequence models. The approach is centered on the concept of "generalized belief states", statistics of past observations that satisfy a few criteria: (1) they are sufficient for predicting future data, (2) they can be recursively updated as new observations come in, and (3) they are low-dimensional, allowing for visualization and interpretation. I show that such generalized belief states can be mapped to the internal activations and dynamics of a sequence model, allowing for decoding and manipulation of the model's representations. I illustrate the ideas using a tractable toy model, a transformer trained on a simple HMM stochastic process, where we will see that the KV cache plays a key role.
This post is directly inspired by the 2024 paper "Transformers Represent Belief State Geometry in their Residual Stream" by Adam Shai, Paul Riechers, and collaborators. That paper introduced the idea of studying belief states in transformers, and proposed a method for doing so using tractable toy models. I recommend reading that paper if you haven't already, though it is not a prerequisite for understanding my post. Section 5 compares this approach with the one developed in that paper.
2. Belief states
We start at a general level, by considering the problem of sequence prediction. Imagine that we observe a history of previous tokens and then wish to predict the next token . We assume that sequences are drawn from a stochastic process . For now, it does not matter whether this process comes from real-world data or a generative model.
Before proceeding, we introduce a bit of notation. indicates the token alphabet, indicates the set of finite-length sequences (including the empty history ), and indicates the set of probability distributions over the alphabet . We write for the set of histories with positive probability under the stochastic process.
2.1 Hidden Markov models
To optimally predict the next token after observing history , we must compute the conditional distribution . We may now ask: what information should we track in order to compute this distribution? How should this information be updated as new tokens arrive? Does this information represent some unobserved latent aspect of the stochastic process?
These questions have a straightforward answer when the stochastic process is described as the output of a hidden Markov model (HMM). Given an HMM description, we can write the probability of any history as [1] where is the hidden state of the HMM at step , is the probability of emitting token and transitioning to hidden state from hidden state , and is the initial distribution over hidden states. Using this expression and Bayes' rule, the next-token distribution can be written in a factorized form as Here, is the Bayesian posterior distribution over the hidden state, conditioned on the observed history . This posterior distribution corresponds to the beliefs of a Bayesian observer about the underlying states of the generating process, and in the literature, it is called a belief state. [2]
Belief states satisfy two important properties: sufficiency and recurrence. Sufficiency means that the belief state allows us to predict the next token just as well as if we knew the whole history , as seen from the prediction map in Eq. (1a). Recurrence means that, after observing a new token , the updated belief state can be computed from and alone. In particular, using Bayes' rule, we can write the update map as
In addition to sufficiency and recurrence, belief states have several other attractive properties. For instance, the prediction map (1a) is time-independent and linear in . Time-independence lets us interpret belief states at different steps in the same way; linearity lets us interpret predictions as convex mixtures of those made by individual hidden states. The update map (1b) is also time-independent and "nearly" linear, being a ratio of two linear functions of the belief state. (In fact, without loss of generality, we may instead consider "unnormalized" belief states , which update in a purely linear way . [3] )
In practice, belief states are often encoded as nonnegative vectors: where is the number of hidden states of the HMM. In this way, each belief state is a nonnegative -dimensional vector that sums to 1, so it belongs to a -dimensional affine subspace of . For HMMs with few hidden states, belief states belong to a low-dimensional space, allowing for easy visualization and interpretation. Also, in this space, belief states often exhibit a remarkable fractal structure, which arises from the recursive nature of the update map. [4]
2.2 Example
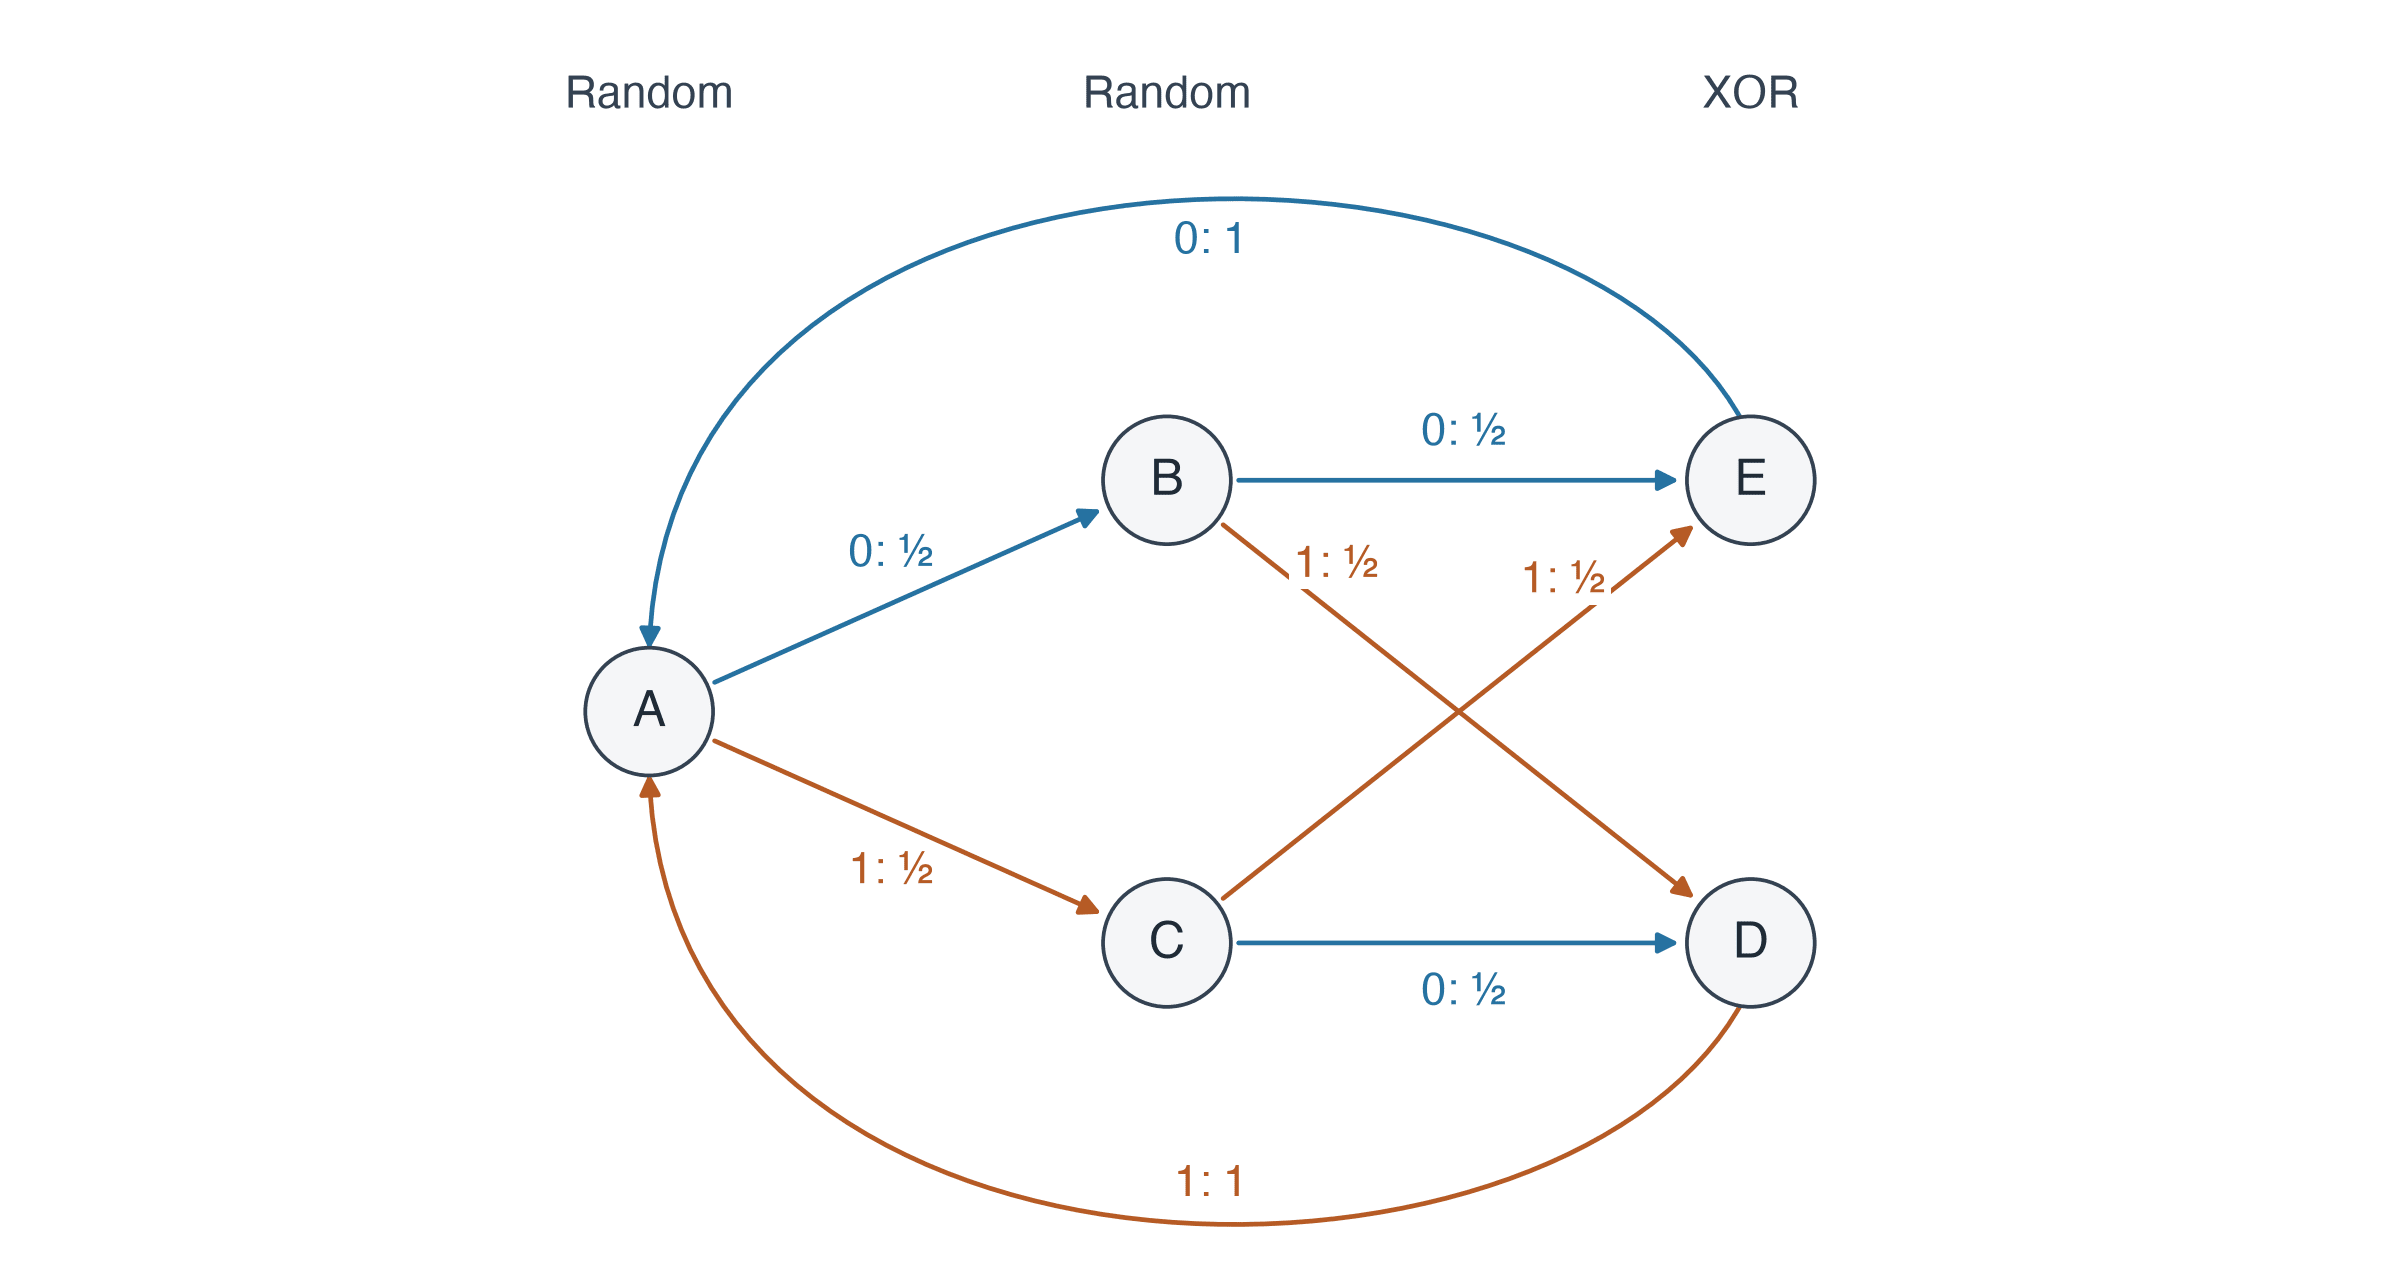
To make things concrete, we now introduce a running example: a stochastic process called MRRXOR that is generated by an HMM with five hidden states. [5] The HMM emits two independent random bits, then their XOR, and then resets. In addition, at each time point, the hidden state can jump to another random hidden state with probability ; if this random jump occurs, it does not emit a token and is immediately followed by an ordinary transition. The HMM is shown in the following figure, with each transition labeled by its emitted bit and probability. (For visual clarity, the random jumps between hidden states are not shown.)
Next, we illustrate the geometry of belief states for this HMM. We compute the belief states after each of the possible histories of length . Each belief state is a normalized nonnegative vector that belongs to a four-dimensional affine hyperplane of .
We visualize these vectors using principal component analysis (PCA), showing all six pairs of the four non-trivial principal components. Each belief state is colored by the last two tokens of the history, with its point area proportional to the history probability. Black dots correspond to each of the five hidden states A–E.
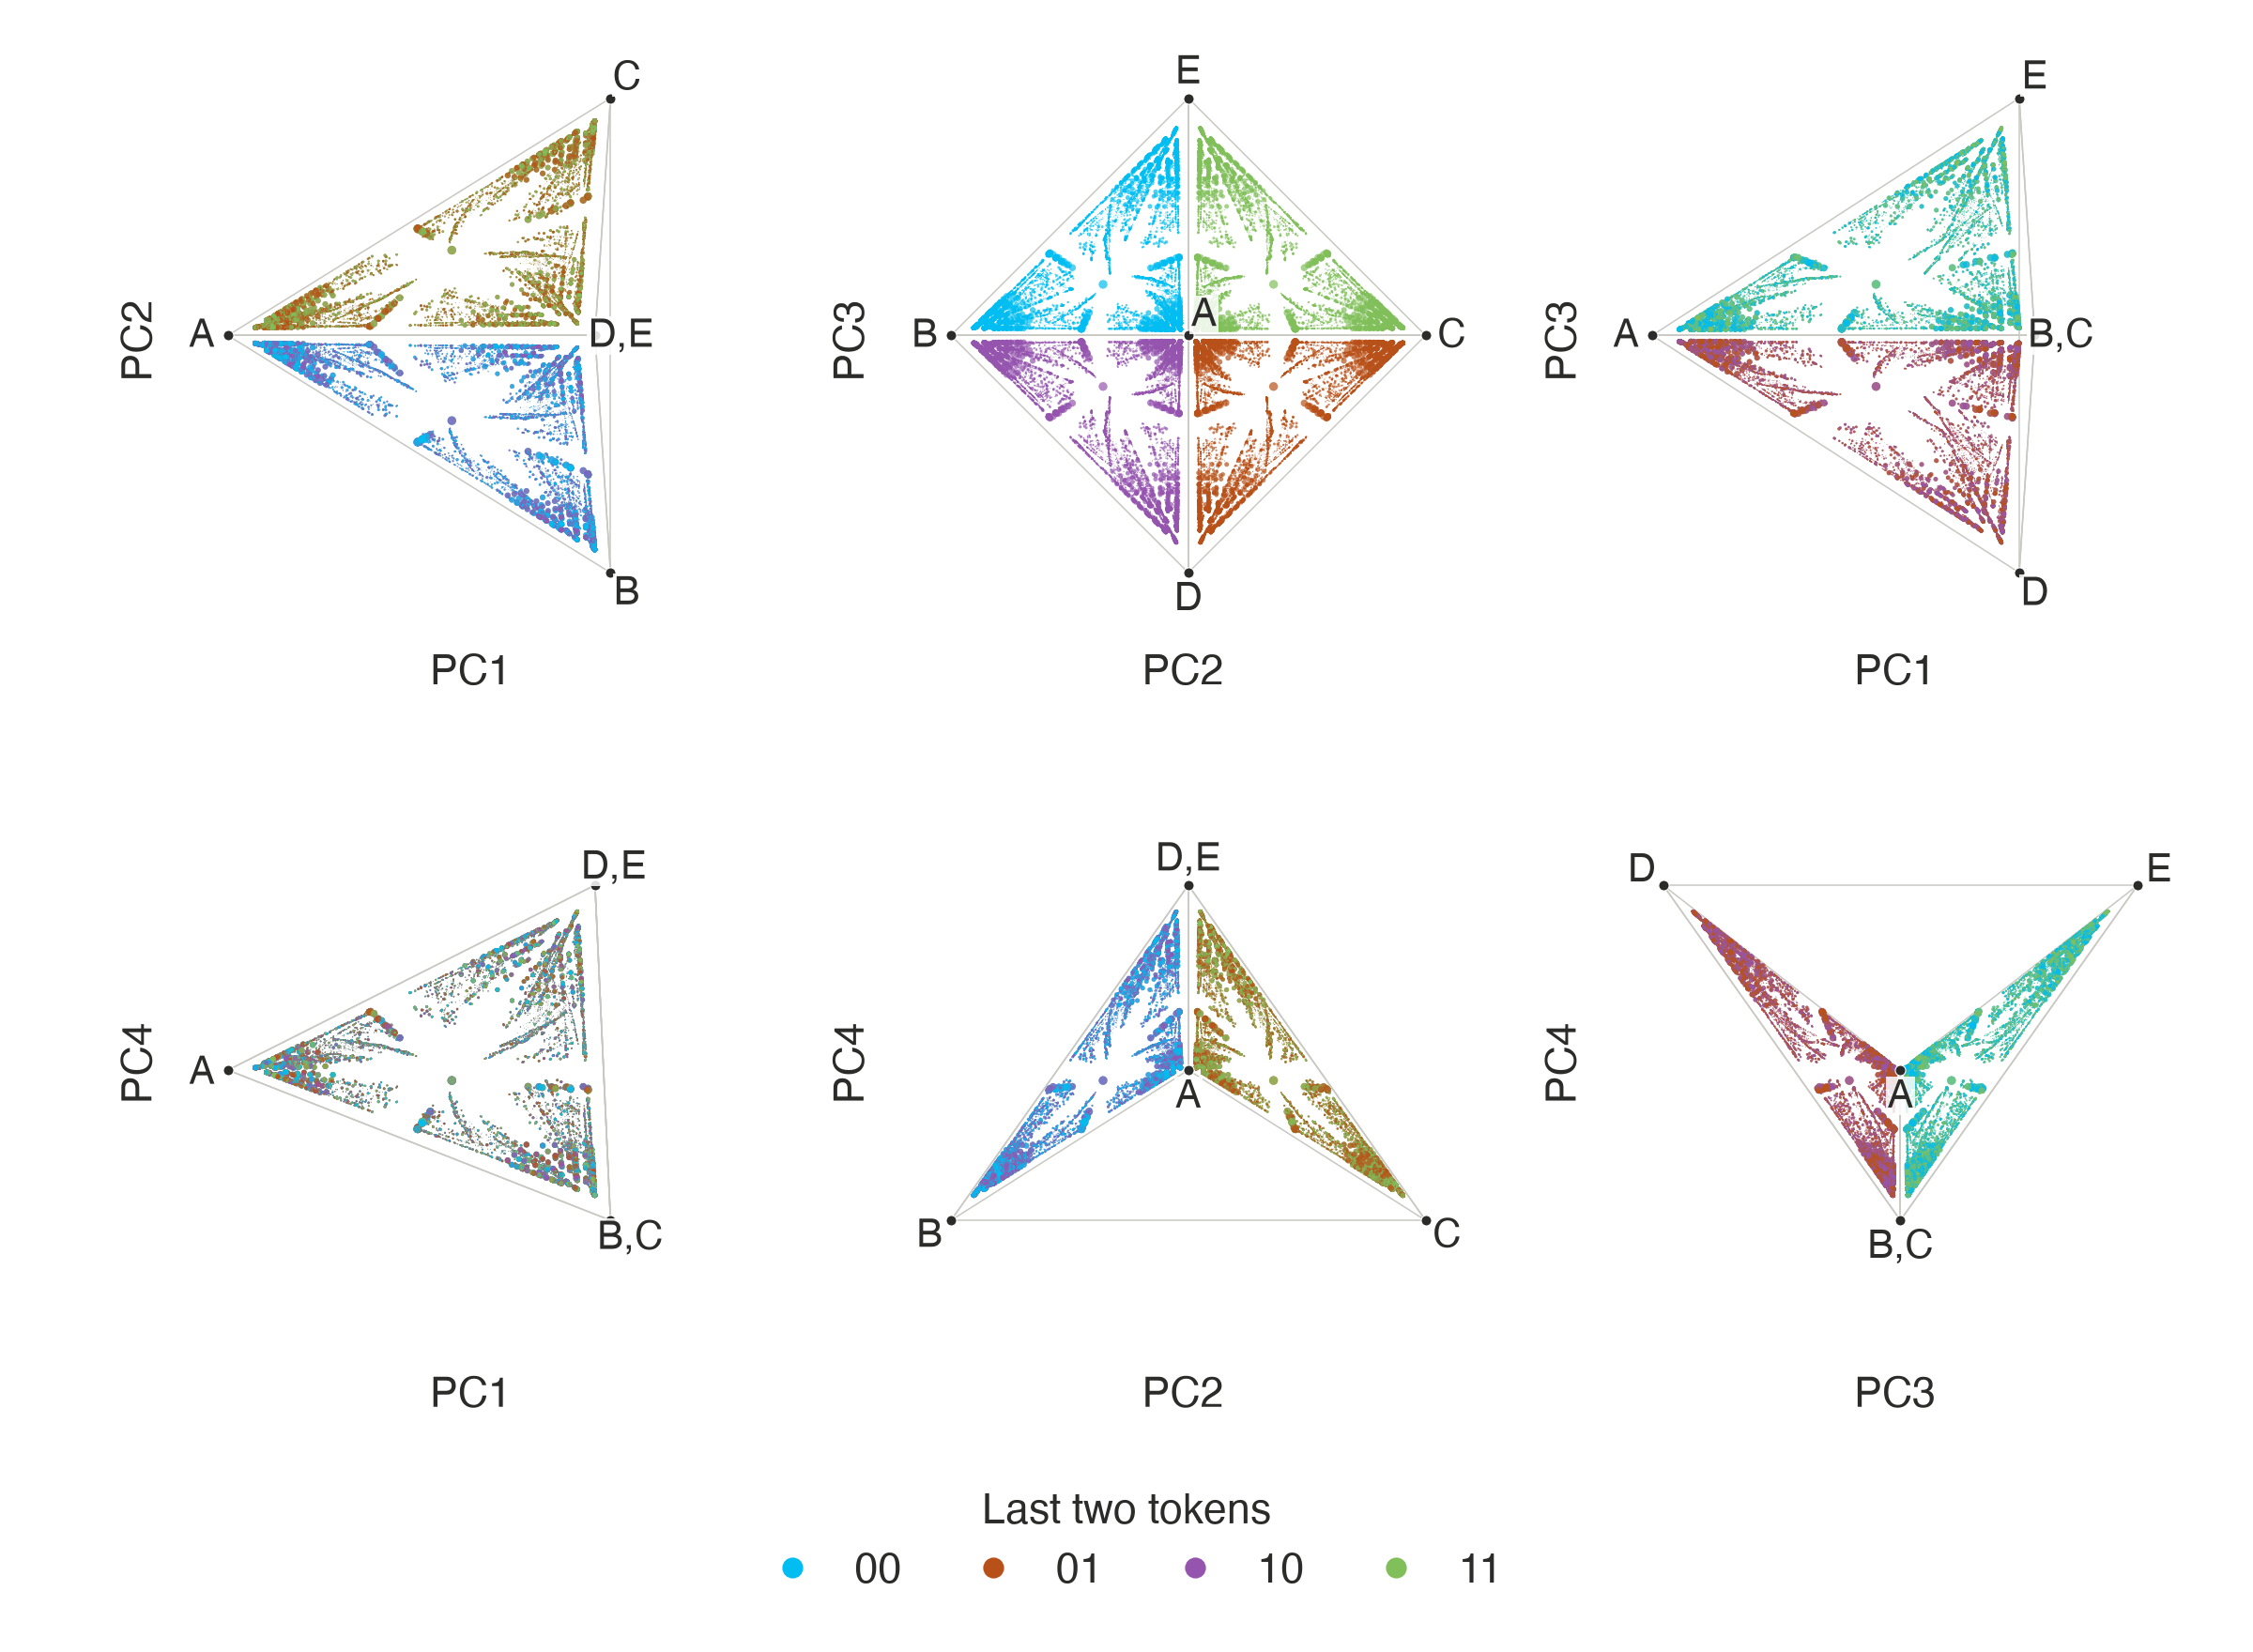
PC1 largely tracks the probability of the "reset" state A, i.e., the belief that an XOR triple has just been completed. PC2 separates histories by their last token. PC3 s
NotebookLM's AI podcasts were my favorite way to study, but ChatGPT Dots might change that
I don't think my professors would be particularly thrilled to learn just how much AI is involved in my study routine, but if there's one thing I've learned in the last two years, it's that AI can be an invaluable tool for learning when used the right way. Pay attention to the last bit of the sentence. It's super important.
Harry Glorikian’s ‘Invisible Interface’ Sits Behind The Scenes
5 Key Reasons AV1 Will Play a Big Role in WebRTC Streaming
In this blog, you will learn why AV1 is getting closer to practical use in WebRTC-based real-time interactive streaming. We cover rapid progress in live AV1 encoding on GPUs and ASICs, widening browser and device support, and new WebRTC compatibility work like SVC and RTP payload formats. You will also see how Red5 Pro’s XDN and LCEVC can lower compute costs and expand device reach as AV1 adoption accelerates.
Advances supporting the next-generation AV1 codec have intensified over the past year, adding new urgency to the question of when the technology might become useful in WebRTC-based real-time interactive streaming applications.
There’s no question live video encoding supported by AV1 would benefit real-time streaming every bit as much as it stands to benefit traditional HTTP streaming. The codec achieves bitrate reductions in the range of 30%-40% compared to HEVC/H.265 and 60%-70% relative to AVC/H.264. Moreover, AV1 is available royalty-free with major tech sector backing through the Alliance for Open Media (AOMedia), whose members include Amazon, AMD, Apple, Cisco, Google, Hulu, IBM, LG, Meta, Microsoft, Netflix, Nvidia, Intel, IBM, Samsung, and many other leading players.
But the amount of computing power it takes to run the encoding and decoding processes has been a major impediment to AV1 adoption, especially when it comes to encoding at live video frame rates. As demonstrated in countless tests, there’s been no practical way to use AV1 to encode video in real time except at very low levels of resolution. For example, a series of recent tests conducted by cloud CDN and compute platform operator Cloudflare found that even if all 48 cores of the top-line AMD EPYC 7642 CPU processor were used to encode a 4K clip commonly used in such testing, it would take 43 seconds to encode two seconds.
But the perspective on the possibilities is shifting rapidly. And we at Red5 Pro are paying close attention to developments.
1. AV1 Live Encoding Is Closer than Ever to Commercial Viability
In 2021, Google released its desktop Chrome 90 browser with an AV1 encoder optimized for video conferencing with WebRTC. The encoder is targeted to two- to four-core CPUs for 2 Mbps transmission of 720p video at 30fps. This points to the fact that encoding AV1 for low bit-rate transmissions at sub-1080p levels is now doable on most PCs, which means the codec can be widely used to get decent-quality video over low-bandwidth mobile links that are the sole means of internet access in many parts of the world.
Cisco took another step in this direction in 2021 on the fringes of its Webex video conferencing service. The company now gives users the option to turn on live AV1 encoding to improve the quality of shared displays of video clips during conference calls.
Anyone on such a call with a device capable of decoding a low-bitrate AV1 stream will see the clip with much greater clarity. Cisco said it expects to expand the use of AV1 on Webex over time but had not announced any further steps as of YE 2022.
A much more dramatic sign of progress on the AV1 encoding front came in late 2022 with the introduction of powerful new AV1-enabled graphics engines by Intel, AMD, and Nvidia. As of this writing, for the first time, live AV1 encoding in fast-action gameplay can be executed by some versions of Intel’s Arc Alchemist and Nvidia’s RTX 4000 series running on gaming cards, which became commercially available in October. AMD released its far less expensive RX 7000 platform in early 2023 with no lofty claims for live AV1 encoding. Even so, early comparisons of the three tech companies’ latest advances, like this one reported by PC World, found them more or less on par with one another when it came to AV1 encoding of content for recording and archival usage.
It’s clear the AV1 live streaming barrier has been broken for gamers who want to shell out $1,500 or so to purchase the Intel or Nvidia gaming cards now on sale from multiple vendors. For example, testing of live video encoding with Intel Arc’s AV1 encoder against leading H.264 GPU encoders, as reported by PC World, found that when set to encode HD 1080p video at 3.5 Mbps, the quality of the video is superior to the output of H.264 encoders delivering the content at nearly twice that bitrate.
Of course, GPU cards significantly outperform encoders running on CPU cores or CPU cores enhanced with GPU acceleration, which remain the primary encoding engines in OTT streaming services. But these latest GPU platform advances point to the likelihood that the densification and architectural advances achieved with gaming encoders will be adopted in succeeding generations of hybrid CPU/GPU processors.
Another hardware advance signaling a role for live AV1 encoding occurred at the 2022 IBC trade show in Amsterdam, where RealSprint, the Swedish company operating the Vindral CDN service, revealed it would be introducing AV1 live encoding on its platform using ASIC (application-specific integrated circuit) hardware technology from NETINT Technologies. NETINT’s low-latency 4K AV1 encoder harbingers the emergence of ASICs as a potential game changer in advanced codec operations, according to NETINT COO Alex Liu, as quoted by Streaming Media. “[These applications] can only be met with ASIC hardware encoding,” Liu said.
2. Browser, Player Support for AV1 Decoding Is Gaining Wider Traction
Meanwhile, on the decoding side, there’s been a surge in browser and app support for AV1 software decoding on high-power devices. For now, this means that entities streaming on-demand content can use AV1 encoding with high confidence that a growing share of users will be able to take advantage of the bandwidth savings, which are beneficial to distributors as well as receivers.
The Google-backed Chrome browser and apps based on Android 10 or later can support software-based AV1 decoding on any device with enough processing power to accommodate the codec. Firefox, too
Modernizing Enterprise Storage: How Automation and AI Are Changing Infrastructure Engineering
Enterprise storage infrastructure rarely receives attention until something goes wrong. Yet behind business applications, databases, analytics platforms, and digital services are complex systems responsible for storing, protecting, and making data available. As organizations accumulate larger volumes of information, modernizing these environments becomes an engineering challenge involving architecture, performance, connectivity, validation, and operational risk.
For Nikhil Kumar Aedla, a Principal Data Storage Engineer, enterprise storage modernization involves more than transferring information between platforms. His work supporting a multi-petabyte storage migration brings together infrastructure planning, storage area network (SAN) connectivity, automation, validation, and AI-assisted operational analysis. The approach reflects a broader question facing infrastructure teams: how can organizations modernize large storage environments while maintaining control over the systems and data that depend on them?
Why Enterprise Storage Modernization Is More Than a Data Transfer
Large enterprise storage environments often contain infrastructure introduced over many years. Different generations of storage platforms, interconnected hosts, application dependencies, and established operational procedures can make modernization difficult to coordinate.
Moving data from an older storage environment to a newer platform requires an understanding of how applications access storage, how SAN paths are configured, how capacity is allocated, and how performance requirements influence migration sequencing. Maintenance windows, compatibility, rollback planning, and business continuity also need to be considered.
At multi-petabyte scale, treating the migration as a single transfer overlooks the relationships between infrastructure components. Each stage needs appropriate preparation and validation so that issues can be identified and addressed before the next stage proceeds.
Nikhil’s experience supporting enterprise storage modernization reflects this interconnected nature of the work. Storage architecture, host dependencies, migration planning, and operational coordination need to be considered together rather than managed as isolated technical activities.
Building a Structured Migration Strategy
A phased migration approach provides a way to organize complex infrastructure changes into manageable stages. Instead of moving an entire environment as one operation, engineers can plan migration waves around application priorities, infrastructure dependencies, maintenance windows, and performance requirements.
Preparation begins with understanding the existing environment. Capacity, SAN connectivity, host access, application relationships, and target-platform requirements all influence the migration sequence. Engineers must also establish how each stage will be validated and what procedures will apply if the expected conditions are not met.
Nikhil’s work has involved pre-migration readiness checks, dependency reviews, migration sequencing, and coordination across technical teams. These activities help define the operational requirements for each phase and establish what needs to be checked before and after data movement.
A phased approach also creates opportunities to review earlier migration activities before proceeding with subsequent stages. This makes documentation, consistent procedures, and clear status tracking important parts of the overall engineering process.
Using Automation to Make Infrastructure Work Repeatable
Large storage environments generate substantial amounts of routine administrative work. Engineers may need to collect configuration information, check connectivity, validate capacity, compare source and target settings, track migration progress, and prepare operational reports.
When these activities depend entirely on manual execution, maintaining consistency across repeated migration tasks can become difficult. Automation provides a way to standardize predictable procedures and make their execution easier to track.
In Nikhil’s storage modernization work, Ansible, Python, and PowerShell were used to support repeatable infrastructure operations. Ansible can orchestrate defined tasks, while Python and PowerShell can support scripting, data handling, validation, reporting, and platform-specific administrative activities.
The objective is not to automate every engineering decision. Instead, repeatable procedures can be automated while engineers retain responsibility for architecture choices, exception handling, production approvals, and risk assessment.
This distinction matters because infrastructure automation operates within environments where an incorrect change can affect multiple dependent systems. A reliable workflow needs to make its actions, validation steps, and failure conditions understandable to the people responsible for operating it.
Where AI-Assisted Operations Fit Into Storage Engineering
Automation and artificial intelligence address related but different problems. Automation executes predefined procedures, while AI-assisted analysis can help engineers interpret information produced by complex infrastructure environments.
Storage systems generate logs, alerts, configuration outputs, migration status records, and performance information. When an issue involves multiple infrastructure layers, engineers may need to examine information from storage platforms, SAN connections, hosts, and applications before determining what happened.
Nikhil’s work incorporates AI-assisted tools as a support layer for reviewing operational information. These tools can help summarize logs, group related alerts, compare expected and observed conditions, and highlight configuration differences that warrant investigation.
AI can also help organize source and target information into a clearer view during migration validation. Rather than requiring engineers to begin with large collections of raw operational data, an AI-assisted workflow can help direct attention toward specific exceptions and questions.
The output, however, is not the same as a verified diagnosis. An identified pattern or summarized alert needs to be checked against the underlying evidence and the technical context of the environment.
Combining AI Analysis With Human Engineering Judgment
Enterprise infrastructure requires clear accountability for decisions that affect production systems. An AI-generated recommendation may be useful, but it should not automatically become an approved infrastructure change.
In storage modernization, this distinction is especially important when decisions involve data integrity, application availability, connectivity, or recovery procedures. A summary of operational logs can help an engineer investigate an issue, but it cannot independently establish that a proposed action is appropriate for every dependent system.
The operating approach described in Nikhil’s work keeps architecture decisions, production changes, approvals, exception handling, and risk acceptance under engineering control. AI assists with organizing information and narrowing the scope of investigation, while engineers verify the evidence and decide what to do next.
This division of responsibilities allows AI to support operational analysis without bypassing established change-management and validation procedures. It also provides a practical framework for introducing AI into infrastructure environm

262 Blog Posts To Learn About Life Lessons
Let's learn about Life Lessons via these 262 free blog posts. They are ordered by HackerNoon reader engagement data. Visit the Learn Repo or LearnRepo.com to find the most read blog posts about any technology.
'The roots of education are bitter, but the fruit is sweet.' Aristotle
1. 10 Money Lessons I Wish I Knew When I Was 25
Andrew Lokenauth goes over money lessons that everyone in their 20s should know about.
2. This Conversation Changed My Life
 Sahil Bloom details a conversation that changed his life.
3. Cognitive Dissonance Theory and How it Impacts US
 Cognitive dissonance is a psychology theory about how we strive to make sense about conflicting cognitions and behaviours.
4. A Guide to Becoming More Confident in Job Interviews (and in Life)
 One of the most common pieces of advice given to jobseekers is to “be more confident.” But what does that really mean? And how can you do it? The truth is, conf
5. Here's Why High Achievers Feel Like Failures
 The invisible progress paradox is a trap in personal growth.
6. Why the Rich Get Richer and the Poor Get Poorer
 It’s just the way things are and have always been, or is it?
7. Is PHP a Dead Language [Part 2]
 This Slogging thread by Arthur Tkachenko, David Smooke, Limarc Ambalina and khunshan occurred in slogging's official #programming channel, and has been edited for readability.
8. Four Possible Ways to React to Other People's Happiness or Misery
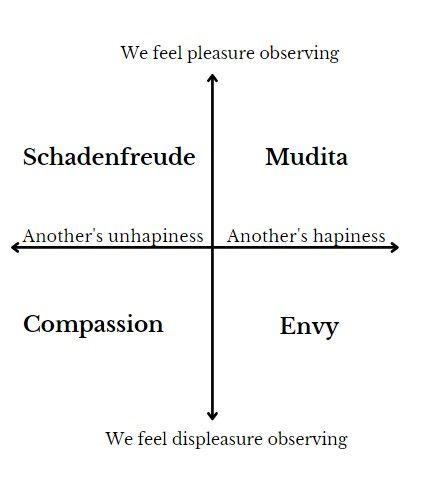 Schadenfreude, Compassion, Envy and Mudita: explaining how we react to other people's fortunes or misery
9. Seven Invaluable Lessons Linux Taught Me
 Oh boy, this is going to be interesting. A freelance writer with a law degree writes about Linux. Just when you thought you have seen and read it all.
10. 4 Steps to Actually Finish your Side Project
 We’ve all seen the graveyard of abandoned projects folders. Desperately competing for attention but failing in the glow of a new adventure or app that will change the world. I use to do that all the time, now I finished 4 apps, and 2 other projects within the last year by applying the following steps.
11. No One Knows That You're Great At What You Do
 This is an article by Eko Adetolani that explains low-effort ways that people can use to get recognition and visibility for their work.
12. How To Be Authentic
 There’s a veneer that people maintain online — and we’ve all done it — showing audiences a polished, glowing side of themselves no matter what else might be going on in their lives.
13. What I Learnt from Jordan Peterson
 I hadn’t heard of Jordan Peterson in December, but the second I watched his videos online I was hooked.
14. 3 Life Lessons From John Grisham’s Writing Habits
 Adopting a stoic mindset, employing consistent habits, learning to enjoy improving in our craft could bring meaningful insights into our efforts.
15. How to Be Good Mentor for a Fellow Designer
 About to become a design mentor? Use our guide to navigate through this journey and avoid pitfalls.
16. Die With Zero Regrets and 100% Fulfillment
 How to die with zero regrets and 100% fulfillment?
17. Why Feeling Behind Means You Are Ahead
 If you're playing the long exponential game and feel like you're behind, you're not behind. You're exactly where you're supposed to

500 Blog Posts To Learn About Literature
Let's learn about Literature via these 500 free blog posts. They are ordered by HackerNoon reader engagement data. Visit the Learn Repo or LearnRepo.com to find the most read blog posts about any technology.
Literature refers to written works, especially those considered of superior or lasting artistic merit. Literature is vital for cultural preservation, fostering critical thinking, empathy, and providing insights into the human condition across generations.
1. The Trail of Death
There's sure some sort of hoodoo on these Antarctic expeditions
2. 'It is Some Horrible Inhabitant of Space, Something Unknown to us on Earth'
 They were moving sluggishly along the red light, seeming to flow rather than crawl.
3. He Was Trapped—Two Miles Below the Earth
 Impossible! What sort of creatures would they be, that could live two miles beneath the surface of the earth?
4. There Was No Struggle, No Attempt at Flight or Resistance
 They could see one another, but it was impossible for them to make their voices heard above the rasping of the beetles' legs.
5. The Lord of Space
 On the day of the next full moon every living thing on earth will be wiped out of existence
6. Orris Led the Way to a Great Underground City
 It was now two years since Edwin Leland bought the estate for a song and took up his residence in the gloomy old house.
7. A CRITICISM OF CHRISTIANITY
 A religious system so many-faced and so enduring as Christianity must necessarily be saturated with truth even if it be not wholly true.
8. The Invisible Death: Out of the Hangman's Hands
 "You speak," said Von Kettler, jeering, "as if you really believed that you had the power of life and death over me."
9. Of the eleventh horn of Daniel's fourth Beast
 A Seer, Επισκοπος, is a Bishop in the literal sense of the word; and this Church claims the universal Bishoprick.
10. My Friend Stumbled on an Invention That Could Revolutionize Human Life
 Certainly, if ever a man found a guinea when he was looking for a pin it is my good friend Professor Gibberne.
11. Murder Madness! 7 Secret Service Men had Completely Disappeared
 The engines of the Almirante Gomez were going dead slow. Away up beside her monster funnels her siren blew dismally
12. Healing From Verbal Abuse
 An Essay Concerning Humane Understanding, Volume II, by John Locke is part of HackerNoon’s Book Blog Post series.
13. The New Religion
 EVERY great religion has as its psychological reason for existence the mission of compensating for some crying, unsatisfied human need.
14. The Story of the Last Trump
 “Now to God the Father, God the Son——”
15. The 5 Best Batman Comics for New Readers
 There are only a few characters that have a bigger comic book catalog than Batman. Here are the best Batman comics for new readers.
16. The Motion of the Planet Neptune Had Become Very Erratic
 Ogilvy had already called attention to a suspected retardation in its velocity in December.
17. The Best Places to Read Digital Comics
 There are several places to read digital comics. Some of these places include Marvel Unlimited and Prime Reading.
18. OIL-LAMPS OF THE NINETEENTH CENTURY
 The oil-lamp and the candle were the mainstays of artificial lighting throughout many centuries.
What to do if you hit a deer
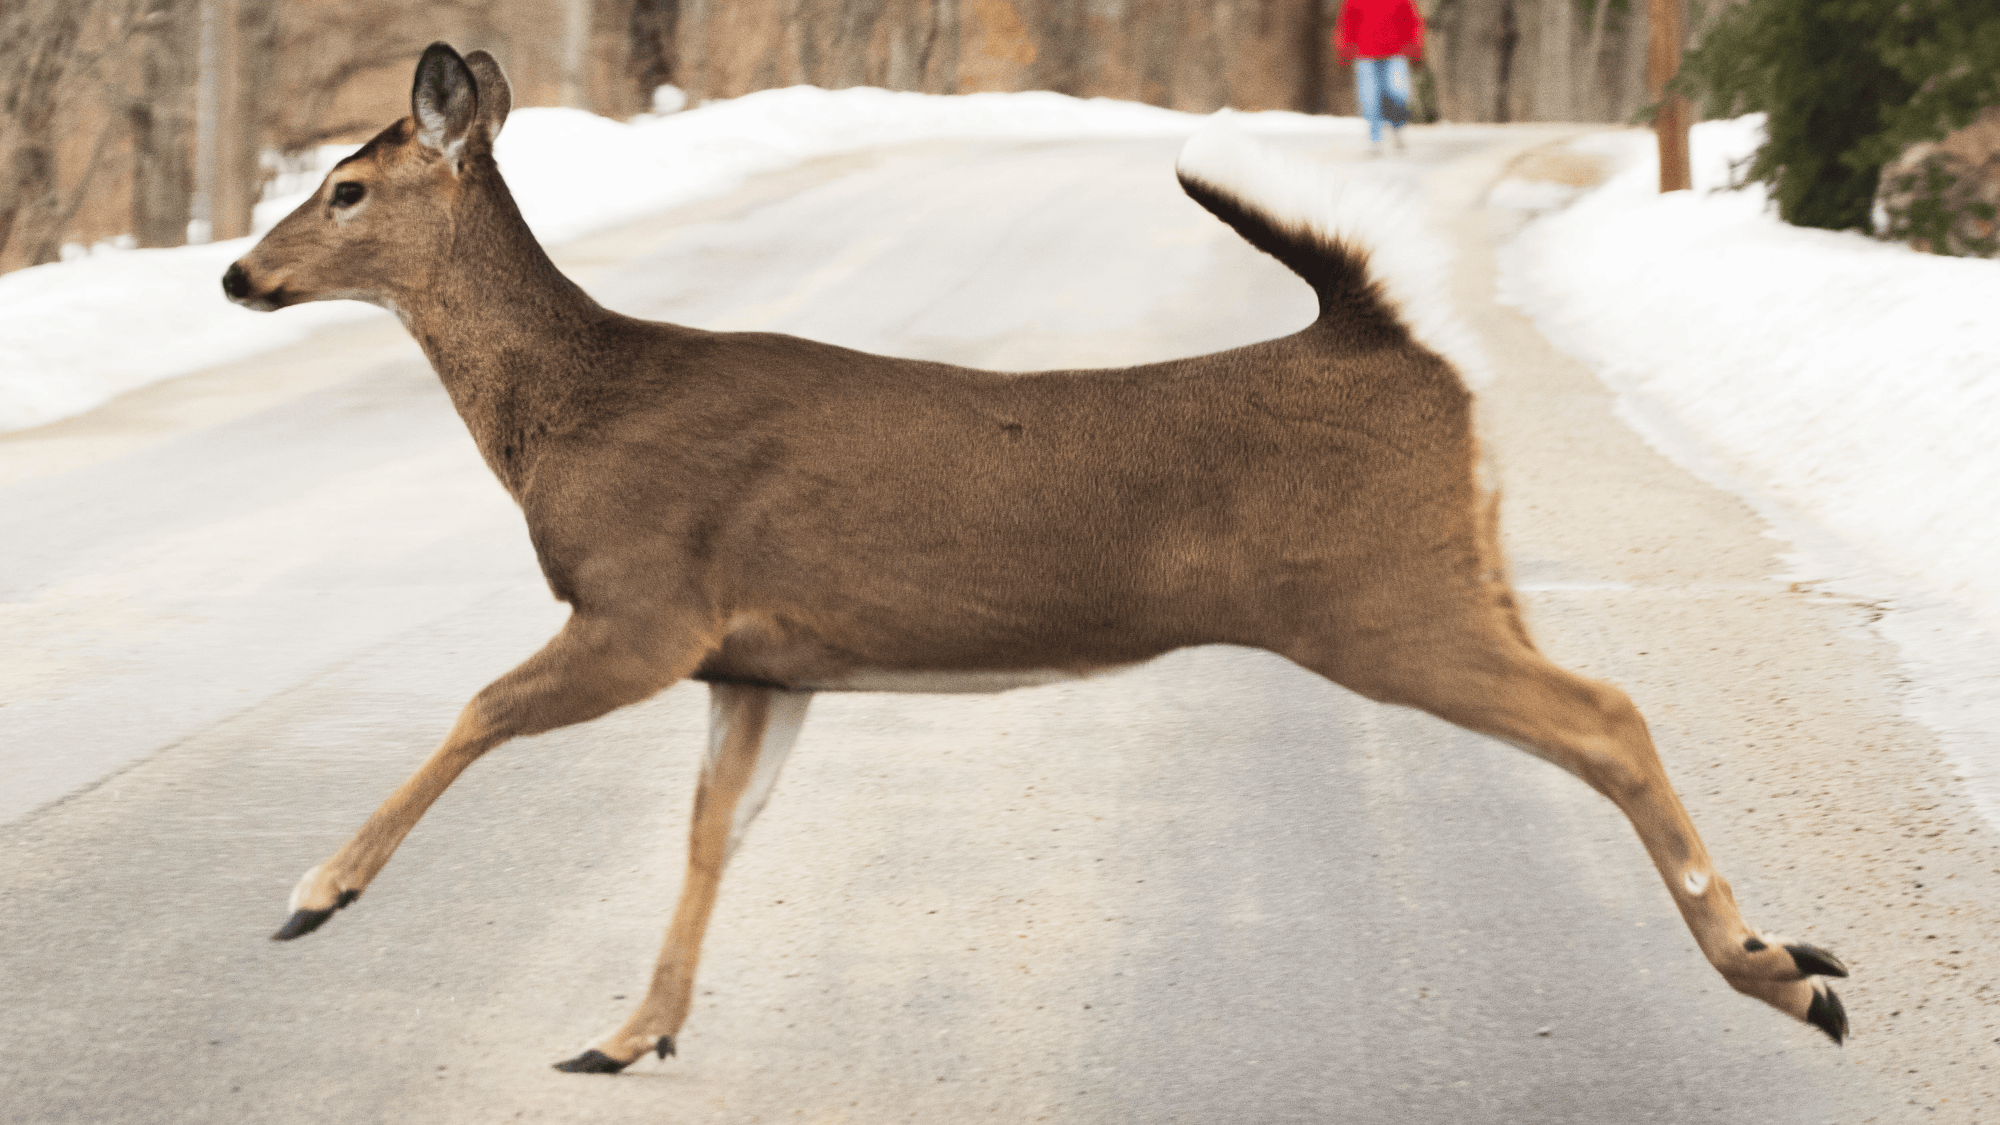
When you think of the fall season, chances are that gorgeous foliage, brisk sweater weather, and Halloween decorations come to mind. Deer, on the other hand, think of sex.
Deer breeding behavior, known as the rut, aligns with the changing length of daylight. As daylight decreases, buck (male deer) and doe (female deer) hormones increase. While in southern states the rut can last several months, it only runs for a short period of time during the fall in the Northeast.
During the rut, bucks seek out does that are ready to breed, and the amorous pursuit can be intense. Because some bucks are so obsessed with breeding, they can eat little and burn through up to 20 percent of their body weight during the season. And just like love-crazed high schoolers, deer during the rut are more distracted and less cautious, as well as more active during the day than they usually are.
“During this period, many yearling bucks leave their birth areas in search of new territory, sometimes dozens of miles away. At the same time, adult bucks are actively roaming their home ranges in pursuit of doe, often chasing those they encounter,” according to Raven Ridge Wildlife Center in Pennsylvania.
What’s more, “The end of daylight-saving time means more vehicles will be on the road during dusk and dawn, which are the peak hours for deer movement.”
In fact, most deer-vehicle accidents take place in October through December. While there are things you can do to lessen your chances of hitting one—such as staying alert and paying close attention when you see deer crossing signs—sometimes accidents are unavoidable. So what should you do if you hit a deer?
Safely pull over and turn your emergency flashers on. While your instinct might be to go see the deer or move the body off of the road, resist the temptation. Care for any injured passengers, and call 911. The dispatchers will send the appropriate authorities to help.
And if you narrowly avoided one deer, remember that, “deer often travel in groups and walk single file,” per the Raven Ridge Wildlife Center. “So even if one deer successfully crosses the road in front of a driver, it doesn’t mean the threat is over. Another could be right behind it.”
The post What to do if you hit a deer appeared first on Popular Science.
Enterprise AI is waiting for its PageRank moment
Let’s try a little thought experiment in technology-fiction: what would have happened if Larry Page and Sergey Brin’s PageRank, back in 1998, had failed to attract its first investors? Google didn’t invent the search engine: there were plenty of them before, from AltaVista, Excite, Lycos or others who were counting words on pages and selling their results page to the highest bidder, to catalog or portal concepts such as Yahoo! or AOL, that attempted to capture the users’ attention as much as they could to be able to serve them advertising, the more the better. Imagine if these concepts would have gone the distance, and deprived us of the web that resulted from Google’s easy and efficient way of searching …
What did Larry Page and Sergey Brin realize? They adapted and extended the citation index (or its consequence, the citation impact), a system that they knew worked for academic literature (remember, these guys were graduate students working on their Ph.D., and thus reading academic papers like there was no tomorrow!), and moved it into a new context: the web. They realized there was an underused signal, relationships among pages, and used it to generate a metric, weighting links according to the importance of the pages providing them, that not only allowed them to index the web, but also to define attention as a social construct: a page is important when other pages link to it with a certain term.
What’s today’s underused signal in corporate AI?
As I’ve said several times, corporate AI is completely different from individual AI: companies don’t need just answers to questions, what they need is persistent memory and state, feedback learning loops, embedded cybersecurity, logs that can be tracked and not manipulated, etc.
So far, companies are building these required scaffolding using twentieth-century tools such as Python, and AI agents are proving to be smart enough as to escape from these containments and do all sort of bad things — not because they are intrinsically evil (they cannot be), but because the goals and the guardrails are badly defined, or due to excessive permissions, prompt injection, or weak isolation. These companies are trying to define these properties by repeatedly assembling application by application, rather than supplied coherently by the platform.
However, companies are repeatedly making all sorts of decisions about suppliers, customers, inventory, pricing, service, etc. Those decisions are constantly generating evidence of what works and what not, provided that the company is smart enough to capture them. What if we could evaluate AI by whether the company learns and improves, beyond the quality of individual outputs? What if AI optimization becomes more important than having access to bigger models?
The competition moves from model capabilities to system performance
A company does not just need a very powerful AI model: it needs an architecture that coordinates capabilities toward its goals. Researchers writing on Berkeley’s AI research blog explicitly describe the shift toward compound AI systems, where system design can offer better returns than further model scaling.
Other experiments, such as FrugalGPT or DSPy are specific precedents for making model selection subordinate to results: FrugalGPT demonstrated that model cascades can match the strongest individual model with up to 98% lower cost on its evaluated tasks, and DSPy showed that optimized pipelines using smaller models can compete with approaches using much larger proprietary models.
What makes the next step consequential? The ability to learn across executions. If we manage to make each interaction inform subsequent decisions across the relevant population, we can achieve a substantial advantage. And world models
Xpeng just launched a $20,800 electric SUV, and US automakers should be paying attention
[程序员] 压缩的尽头是自指?从 LZMA2、PAQ8PX 到 zstd/ZIP/RAR Quine,我折腾了一遍“自包含压缩包”
最近把之前关于压缩的各种折腾整理成了一篇长文,发在博客上,想搬来论坛和大家聊聊。
一开始只是想给博客离线包找更强的压缩算法:7-Zip 的 LZMA2 已经很能打,但我不信邪,又试了 ZPAQ 、PAQ8PX 、NNCP 、cmix 。结果挺有意思:
- ZPAQ:一分钟左右把 16MiB 压到约 3.5MiB ,老算法但速度和压缩比还挺平衡;
- PAQ8PX:压到约 3.1MiB ,本次冠军,但花了一个半小时、吃了 30GiB 内存,解压同样痛苦;
- NNCP:FFmpeg 作者 Fabrice Bellard 的 Transformer 压缩算法,RTX 4090 上跑了一个半小时,结果 4.1MiB ,还没 LZMA2 高;
- cmix:测试时压到一半崩溃,内存和耗时也很夸张。
结论大概是:追求极限压缩比,PAQ8PX 很强;日常使用,LZMA2 的 7-Zip 依然是最稳的选择;想在小文件上再挤一点,ZPAQ 可以试试。
更有意思的是后半篇:继续折腾“自包含压缩包 / Quine 压缩包”——也就是压缩包里包含一份和自身字节完全相同的副本。之前做过 7z Quine ,这次又让 AI 研究了:
- zstd Quine:利用可跳过帧、RAW block 和 XXH64 校验值构造,最终做成
.tar.zst,Windows 资源管理器也能直接打开;文章里附了完整生成代码; - ZIP Quine:利用成员数据重叠绕过窗口限制,7-Zip 和 libarchive 能正常解压,但 Python
zipfile会因为检查压缩数据越过后续局部头而报错,算是一点兼容性代价;文章里也附了生成器; - RAR Quine:原理上也能做,AI 也生成出来了,但因为 RAR 不是开源软件,文章里只放了生成后的样例供研究。
文章里还有一段让我挺感慨的:这些代码我基本看不懂,但 AI 就是能把问题解决。复杂格式、校验值构造、兼容性坑,全都硬啃下来了。于是最后也忍不住写了点关于 AI 和“记录还有没有意义”的感想。
原文在这里:《关于压缩的各种探索》
感兴趣的朋友可以聊聊:
- 你用过最离谱但确实有效的压缩算法是什么?
- 极限压缩比和可用性之间,你会怎么选?
- 对这种“压缩包包含自身”的 Quine 玩法,有没有其他格式可以继续挑战?
- AI 生成这种复杂但能跑的代码,你觉得是解放生产力,还是让人越来越看不懂基础设施?
欢迎拍砖、补充算法和格式,也欢迎试试文中的 zstd/ZIP 生成器~
L4需要更大的模型,芯片得换个造法了
(本文作者为 互联网江湖,钛媒体经授权发布)
文 | 互联网江湖,作者 | Evin,编辑 | 刘致呈
如果你长期跟踪智驾行业,会察觉到一个变化正在悄然发生:发布会上的主角,正在从“技术”换成“量产”。
2026年以来,L4落地声量明显抬升,城市NOA渗透率持续走高,车企量产军备竞赛全面打响。
从“技术竞争”换轨到“量产竞争”,已是行业明牌。
但换轨途中横着一个尴尬的现实:多数通用芯片正在拖量产的后腿。
车规环境下,通用芯片的“不可能三角”凸显:账面算力与有效算力相差悬殊,利用率往往只有30%—40%。
这笔被浪费的差价,堪称L4规模化路上一笔“隐性税”。
10月29日,转机出现了。
XHEART新芯航途CEO李宗霖正式发布大模型芯片X7 Ultra:700 TOPS大模型算力、超大核NPU、高精度专用算子加速、Armv9车规级CPU。
这颗芯片自创立之初就沿着一条另类的路线前行——“大模型定义芯片”:不追求通用性的面面俱到,而是由大模型反向定义硬件。
这有点像当年的DeepSeek。
DeepSeek的出现为AI行业指明了,大模型不必沿着旧算力逻辑硬堆也能跑出新的可能性,此后AI应用如雨后春笋般生长。
如今,X7 Ultra则为L4验证了,L4的落地也不必拘泥于通用芯片的算力瓶颈,L4量产落地,有了一条新路。
自此,L4量产的DeepSeek时刻来了。
大模型芯片发布,L4落地有了“新基建”
大模型定义芯片不是实验室里的炫技,而是量产需求倒逼出来的必然产物。
推动力首先来自市场端。
最近一段时间,车企新车的大模型和辅助驾驶能力正在全面标配。
工信部数据显示,2026年以来乘用车组合驾驶辅助渗透率已达70.5%,NOA渗透率超过30%,首批L3车型也开始在特定区域上路。
随着端到端的智驾普及,接下来,车企的每一款新车立项,都会用上更强的芯片。

与此同时,AI模型体量越来越大,对芯片性能的要求也越来越高。
Momenta CEO曹旭东判断,未来规模化L4需要10B—100B量级的大模型来应对复杂长尾场景。
新一代大模型规模化上车,带来的直接问题是:通用芯片接不住。
为什么接不住?
因为量产赛场上最难的,是三条互相拉扯的硬指标。
首先,要“跑得起来”,就得满足算力和功耗的硬性要求——10B—100B的模型要在几十瓦功耗、毫秒级延迟下运行,通用芯片为灵活性预留的架构冗余,在车端反而成了负担,大量算力耗在架构开销而非有效计算上。
其次,要实现“规模上车”,那么对应成本——成本必须降到付费方持续买单的水平,并为折旧运维留出利润空间。而在通用芯片的定价体系下,车企很难算平成本账。
最后一点,也是最重要的一点:安全。L4阶段责任主体转移到主机厂,安全成为“生死线”,芯片的计算行为必须可预测、可验证——同样的输入产生稳定输出,负载变化时延迟可控,结果可被完整追溯。而时快时慢、利用率飘移的通用平台,撑不起安全底线的工程化验证。
最终,结论只有一个:市场需要一颗从大模型需求出发设计的大模型芯片。
L4的落地发展,其实有点像前几年AI行业。
ChatGPT火了之后,模型对算力的需求越来越大,直到DeepSeek给AI行业开辟了一条新路。
从底层逻辑上来看,大模型定义芯片,恰如当年DeepSeek的发布。
DeepSeek证明了AI大模型不必硬堆参数、硬烧算力卡,通过架构创新提升AI infra层的效率,也能跑出规模应用。如今,在L4这个赛道,X7 Ultra发布之后,XHEART通过NPU架构创新,再次验证了这条路径。
从这个意义上讲,XHEART和Momenta要做的事情,相当于L4落地的“新基建”。
L4怎么量产落地?
关键核心在于解决几个问题:
第一,从NPU入手,解决效能问题。
传统智驾芯片的NPU由多个小核拼凑,核间数据交互在百GB/s量级,大量算力耗在“内部搬运”上。
大模型定义芯片则从根本上解决了这个问题。X7 Ultra把计算单元聚合成一个超大核,内部互联速率拉到TB/s级。
但仅此还不够,数据能在核内高效流动,计算本身也得高效。
这就是第二点:靠专用算子,解决延迟问题。
Transformer架构里的高频计算,过去在NPU里跑不动、只能绕道CPU,一来一回既费带宽又费时间。
为此,XHEART从2023年起便与Momenta算法团队联合研究模型架构及关键算子,为这些高频算子配备了专用硬件,原生支持FP16/FP32高精度向量计算——关键计算既快,又不丢精度。
高精度带来计算行为的确定与可预测,这正是安全验证的物理基础。
还有,靠整网级工具链重构,解决最终上车的问题.
传统推理是算子逐个执行、中间结果反复写回外部内存;XHEART的做法是把整张网络统一编排、融合,实现“整网内存零拷贝”,结果就是内存带宽消耗降下来了,同一块芯片能跑更大的模型,单位算力的成本自然也就降下来了。
最终实测数据给出了答案:NPU计算利用率98.7%,内存带宽消耗比行业旗舰低80%,能效翻倍。
X7 Ultra的700 TOPS大模型算力,也是在真实量产智驾模型上测得的,前提是量化后模型输出与FP32模型的相似度达到99.99%以上。模型结构不能随意改,精度和驾驶体验不能打折——性能优化从一开始,就要对准量产要求。
实际上,大模型定义芯片,不是在某一个指标上做加法,而是让此前互相拉扯的算力、成本、安全,在同一个架构里被同时满足——它给L4的到来铺平了一条路。
对行业而言,这背后还意味着一场更深层的变化:智驾的竞争逻辑,正从“堆算力”转向“系统竞争”。
过去L2普及阶段,行业信奉“算力越高,智驾越强”的公式,但现在,L4落地要求系统竞争,背后是算力、成本、功耗、安全四者之间的协同。
简而言之,这场比赛的规则变了,从“单项锦标赛”进入了“团体赛”。
这个逻辑在新能源汽车行业已有先例:比亚迪的闪充技术本质上就是“系统竞争”:单靠堆电池容量解决不了补能焦虑——只有当电池、平台、桩、储能在架构层面协同设计,快充才能真正落地。
同理,单靠堆算力也解决不了智驾的天花板。
把镜头再拉远一点,大模型芯片并非孤例,而是专用化AI芯片浪潮中最先被推到台前的场景之一。
芯片专用化、软硬一体早已是大势所趋。
谷歌TPU从诞生之初就只为加速神经网络计算服务,专用芯片正变成AI算力结构中的重要一极。
汽车行业亦然,主机厂不再满足于采购通用座舱或智驾芯片,而是直接参与定义甚至自研专用芯片,L4量产阶段尤甚。
X7 Ultra正是这个逻辑的产物:它对大模型的“适配”不是软件层面的修修补补,而是架构层面的血脉相通——不做算法去适配芯片,而是芯片天然契合大模型计算。
这等于从芯片定义逻辑上,诞生了一个新物种。而这个新物种,不是L4的配套,而是L4量产的前置条件。
从此,L4量产的大门才真正被打开。
L4只是起点,真正的未来在物理AI
在汽车产业链条上,判断一条技术路线的成色,最终要回到一个朴素的问题:它装进车里了吗?
在这一点上,Momenta与XHEART已经交出了答卷。
X7系列的客户车型包括上汽大众ID. ERA 9X/8X、荣威家越07、MG07等,从德系合资巨头到自主品牌头部,这表明双方的软硬协同已跨过“PPT协同”阶段,进入可验证的商业化落地。
同时,也足以见得大模型定义芯片,未来商业化落地的路径清晰。
从智驾技术演进来看,量产本身就是最好的验证场。
只有在真实车型、真实用户、真实路况中打磨成熟的软硬协同能力,才能更好迭代,产品技术,进而带动L4进一步实现规模化。
曹旭东给出的时间表是:L3和L4有望在2028年迎来重要引爆点,2030年走向规模化落地。
加速这一进程的,正是大模型芯片。
当模型需求直接定义芯片,算法、软件、芯片的迭代节拍第一次被拉到同一节奏上,行业进化速度自然会变快。
据了解,基于X7 Ultra的支撑,Momenta发布的R7 Ultra世界模型,参数规模将扩大5—10倍,安全性能同步提升5—10倍以上,推动世界模型从“理解世界”走向“推演世界”。
至此,L4 商业化落地的最后一块拼图,已经摆上了桌面。
但如果只盯着眼前的装车量,仍然低估了大模型定义芯片的价值。
大模型定义芯片的想象力,可能远不止于L4。
它更深的护城河,在于这套研发方式可以迭代延续:一颗为模型而生的芯片,其研发过程沉淀的是可继承的资产——量产模型参与硅前验证的经验、模型与芯片团队联合调试的协作机制、精度与效率之间取舍的方法论……
这些无形资产不会随一代产品退役,而会完整传递到下一代芯片上,支撑未来更大的模型在性能、能效、系统成本和交付效率上持续优化。
这个剧本似曾相识。
当年,英伟达靠CUDA生态绑定AI开发,也是靠芯片架构技术代际更迭能力,统治了AI算力市场。如今,专注芯片、聚焦AI计算、以软硬件协同构建壁垒,大模型芯片的进化逻辑,某种意义上与之高度相似。
这个方向下,XHEART的定位从一开始就不止于智驾,其官方表述是“一家专注于大模型计算的芯片设计公司……并应用于智能汽车,现正向机器人等领域拓展”。
曹旭东也明确指出,大模型定义芯片的思路可以进一步推动机器人以及更多物理AI应用取得突破。
物理AI的命题,是“大模型必须在物理世界的实时约束下运行”——要省电、要低延迟、要成本可控、要行为可验证。
这意味着今天在量产车上被验证过的这套解题方法,明天可以复用到人形机器人、移动机器人,以及一切需要“聪明的大脑+可控的躯体”的物理AI产品上。
也因此,未来芯片的持续研发与规模交付,夯实的不只是Momenta在汽车赛道的长期竞争力,更是两家公司为整个物理AI时代铺设的智能底座。
大模型芯片的前景如何,资本市场的动作往往最诚实。
XHEART的战略融资,参投阵容很有看点:雷诺集团首次投资,奇瑞汽车追加,长鑫科技入局。
产业端,开始真金白银地下注了。
三家资方的诉求各不相同:雷诺看中的是智驾供应链的确定性与下一代车型的计算底座;奇瑞追加投资,要的是量产芯片稳定供给的深度绑定;长鑫科技的入局,则指向存储与算力协同的产业纵深。
诉求不同,但指向同一个判断:一家能把算法能力硬件化的芯片公司,在智驾走向软硬一体的趋势里,有不可替代的位置。
对XHEART而言,这笔融资的意义不在于财务数字,而在于未来芯片持续研发和规模交付的确定性。
芯片是一门重资产生意:从架构立项到流片上车以年计,持续的研发投入、产能保障、车规认证,每一环都需要长期弹药。
50亿融资与已经铺开的客户阵列,就是这种确定性的最佳展现。
眼下,汽车行业的规模化L4是确定的,模型能力与量产能力同步增长的需求是确定的;剩下的变数在供给端。
接下来,谁先贯通了模型、芯片与整车应用,谁就可能真正打开通向未来的那扇门。
而眼下,打开这扇的钥匙已经握在了Momenta和XHEART的手中。
更多精彩内容,关注钛媒体微信号(ID:taimeiti),或者下载钛媒体App
POD-RoPE: Rotary Position Encoding over Physical Observation Distributions for Embodied AI
Mapping the Emerging Social Science of Large Language Models
Wiring Beats Blending: Structure-Aware Compensation for Transformer Downscaling
Calibrated Selective Prediction Using Deep Ensembles for ROI-Based Thyroid Nodule Ultrasound Classification Under Dataset Shift: A Retrospective Evaluation
TransitNet: A Compact Attention-Augmented Deep Learning Framework for Low-SNR Transit Blind Searches