
🤖 AI 资讯

每日 05:00 更新 · 11-01 · 主站 liuch.name ↗
全部标签 →
筛选标签:联邦学习 · 返回个性化推荐 · 清空筛选
AI 资讯

Does Federated Training Degrade Explainability? A Comparative Analysis of Grad-CAM Faithfulness in Centralized vs. Federated Deepfake Detection

arXiv cs.AIarXiv:2610.39483v1 Announce Type: new Abstract: Automated detection has become the essential safeguard against realistic synthetic media, but deploying it at scale requires training on sensitive data from multiple organizations, putting privacy and the transparency demanded by forensic review in direct conflict. Federated learning resolves the privacy side by sharing only model updates rather than raw data, but whether this comes at the cost of trustworthy gradient-based explanations, which analysts rely on to decide whether or not to trust a flagged clip, has not been studied. We present the systematic study of Grad-CAM explanation faithfulness under federated deepfake detection, evaluating an EfficientNet-B4 detector on FaceForensics++ across five federated clients under varying degrees of data heterogeneity. We find that the relationship between federation and explanation quality is non-monotonic: at near-IID (Independent and Identically Distributed Data) and moderate heterogeneity, federated models match or exceed the faithfulness of a centralized baseline, but at extreme heterogeneity, explanations break down entirely, becoming spatially incoherent and, on average, causally misleading. This degradation is not a general cost of federated training but a threshold effect tied to client heterogeneity, and we offer practical guidance for identifying when privacy-preserving deepfake detection can be deployed safely and when its explanations can no longer be trusted. Code and data partitions are available for reproducibility.
2026-10-31 04:00:00 · AI应用,政策监管,搜索RAG,联邦学习,招聘HR,论文
AI 资讯

Governance-Aware Federated Learning for Multi-Agent AI Systems: A Policy-Driven Framework for Trustworthy Collaborative AI

arXiv cs.AIarXiv:2610.38411v1 Announce Type: new Abstract: Federated Learning (FL) enables collaborative model training without exchanging raw data, but conventional FL provides limited runtime governance, evidence verification, fairness assessment, explainability monitoring, and auditability. This paper proposes Governance-Aware Federated Learning (GAFL), which combines independent governance-evidence verification, temporal trust, fairness and explanation assessment, anomaly detection, policy enforcement, normalized aggregation, and tamper-evident audit logging. Client-reported governance values are authenticated, bound to their submitted model updates, and independently recomputed before aggregation. A cross-silo prototype with 10 participants was evaluated on the Adult Income dataset under honest, benign non-IID, biased-data, malicious-update, non-compliant, falsified-evidence, and mixed-threat scenarios. Four methods were compared across five random seeds: FedAvg, FedAvg with anomaly filtering, GAFL without independent verification, and complete GAFL. Complete GAFL intervened on all affected participants at the final round across the evaluated risk scenarios, including identifying 100% of falsified-evidence participants, whereas GAFL without verification identified none of the falsified-evidence participants. Final macro-F1 ranged from 0.7520 to 0.7733 across GAFL scenarios. Complete GAFL required 173.67 plus or minus 26.94 ms of governance processing per round, compared with 3.82 plus or minus 0.79 ms for FedAvg. A strict demographic-parity threshold also caused frequent interventions for honest participants, demonstrating a significant fairness-policy and utility trade-off.
2026-10-31 04:00:00 · AI应用,Agent智能体,扩散模型,联邦学习,招聘HR,论文
AI 资讯

FedHQ: Hybrid Runtime Quantization for Federated Learning

arXiv cs.LGarXiv:2505.11982v2 Announce Type: replace Abstract: Federated Learning (FL) must balance training efficiency and model accuracy across heterogeneous clients. Post-training quantization (PTQ) avoids the extra computation of quantization-aware training (QAT), but can incur greater accuracy loss. We propose FedHQ, a hybrid quantization framework that assigns PTQ or QAT according to clients' hardware and data characteristics. Hardware-based speed estimates and local data-distribution indicators guide coarse-grained global initialization, followed by fine-grained training-based adjustment of selected client strategies. Experiments on three image-classification datasets show that FedHQ achieves up to 2.47x training speedup over FedAQT and up to 11.15 percentage points higher accuracy than FedFQ.
2026-10-28 04:00:00 · 微调蒸馏,联邦学习,招聘HR,论文
AI 资讯

Data-Driven Laplacian-Constrained Personalized Federated Learning

arXiv cs.LGarXiv:2505.07575v3 Announce Type: replace Abstract: Personalization addresses one of the defining challenges in federated learning: statistical heterogeneity among clients. We show that the dissimilarity between the ideal personalized models of two clients can be upper bounded by the dissimilarity of their distributions. Motivated by this, we propose Karula, a data-driven regularization method that constrains pairwise model dissimilarities between clients according to their distributional differences. Distributional similarity is measured using a surrogate for the 1-Wasserstein distance adapted for the federated setting, allowing the method to adapt to highly complex interrelations between clients that approaches based on hard clustering may fail to recover. We propose an approximate projected stochastic gradient algorithm to solve the resulting constrained optimization problem, and prove that it converges at a rate of $O(1/K)$ to a neighborhood of a stationary point.
2026-10-28 04:00:00 · 联邦学习,论文
AI 资讯

Split Federated Unlearning

arXiv cs.LGarXiv:2610.36465v1 Announce Type: new Abstract: Split federated learning (SFL) combines partitioned model execution with federated aggregation to support collaborative learning across distributed Web and edge environments. However, removing learned contributions in SFL is challenging due to cross-partition coupling and historical influence propagation through dual-side aggregation. To the best of our knowledge, we provide the first systematic formulation of Split Federated Unlearning (SFU), encompassing client-wise and class-wise removal, counterfactual retraining, and partition-specific update constraints. We theoretically characterize historical influence propagation and mode-dependent unlearning feasibility, revealing structural limitations of restricted model updates. As an initial solution, we propose SURE, integrating dual-importance estimation, selective parameter perturbation, and importance-guided recovery. Extensive experiments with existing unlearning methods adapted to SFL reveal substantial forgetting-utility trade-offs across model architectures, data distributions, and update modes. SURE achieves competitive agreement with mode-matched retraining at modest additional cost, while further analyses highlight the impact of split position and update constraints on unlearning behavior. These findings establish SFU as a distinct research problem and provide a foundation for unlearning in partitioned federated systems.
2026-10-28 04:00:00 · 扩散模型,强化学习,联邦学习,招聘HR,论文
AI 资讯

Evaluating Federated Vision-Language and Vision-Only Models for Privacy-Aware Breast Cancer Imaging

arXiv cs.CVarXiv:2610.36379v1 Announce Type: new Abstract: Artificial intelligence (AI) shows promise for breast imaging, but limited labeled data, institutional data fragmentation, and privacy concerns hinder centralized training. We investigate a privacy-aware federated learning framework combining pretrained vision-language models (VLMs) with client-level differential privacy. We compare general-purpose CLIP models, biomedical BiomedCLIP, and an ImageNet-pretrained ViT-B/16 baseline on two public breast imaging datasets, with and without differential privacy. We also evaluate a CLIP ViT-B/16 ablation that removes the text pathway. Evaluation includes patient-level ROC-AUC with bootstrap 95% confidence intervals, baseline comparisons, threshold sensitivity, inter-model agreement, and communication cost. Under federated learning, all five models achieve high normal-versus-sick discrimination (ROC-AUC: 0.940-0.990). However, acquisition year alone achieves 0.974 on the same test partition, raising concerns about confounding rather than genuine pathology recognition. Benign-versus-malignant discrimination remains uncertain (ROC-AUC: 0.504-0.637), with all confidence intervals including 0.50. Removing the text pathway preserves classification accuracy while halving communication cost. Differential privacy reduces ROC-AUC by 0.375, attributable to perturbing the full model state rather than only trainable parameters. These findings highlight the importance of evaluating confounding, predictive reliability, privacy implementation, and deployment efficiency when developing federated AI systems for breast imaging.
2026-10-28 04:00:00 · AI应用,搜索RAG,预训练,联邦学习,招聘HR,收购并购,论文
AI 资讯

On the Tradeoffs of On-Device Generative Models in Federated Predictive Maintenance Systems

arXiv cs.AIarXiv:2605.07860v2 Announce Type: replace-cross Abstract: Federated Learning (FL) has emerged as a promising paradigm for preserving client data ownership and control over distributed Internet of Things (IoT) environments. While discriminative models dominate most FL use cases, recent advances in generative models - such as Variational Autoencoders (VAE), Generative Adversarial Networks (GAN), and Diffusion Models (DM) - offer new opportunities for unsupervised anomaly detection in time series analysis, with relevant applications in predictive maintenance (PdM) in critical industrial infrastructures. In this work, we present a comprehensive analysis of VAEs, GANs, and DMs in the context of federated PdM. We analyze their performance and communication overhead under both full and partial federation setups, where only subsets of model components are shared. Building on split-parameter personalized FL, this paper provides an empirical instantiation of shared/private parameter partitioning for unsupervised generative Time-Series Anomaly Detection (TSAD), mapping the split to analysis and synthesis modules across the generative architectures. Our experiments over five clients and two industrial time-series benchmarks reveal distinct trade-offs in model utility, stability, and communication efficiency in heterogeneous cross-silo FL. For the evaluated GAN-based configurations, full federation improves final anomaly-detection utility relative to independent local training, although these models remain less robust than the VAE- and DDPM-based alternatives. For DMs, decoder sharing matches full federation while substantially reducing the communication payload.
2026-10-28 04:00:00 · 扩散模型,强化学习,模型评测,端侧AI,联邦学习,论文
AI 资讯

Correcting Before Adapting: Gradient Correction for Federated Adaptive Optimization

arXiv cs.AIarXiv:2502.02727v4 Announce Type: replace-cross Abstract: Client-drift compensation methods mitigate the impact of data heterogeneity in federated learning (FL). While drift correction is well studied for stochastic gradient descent (SGD)-based FL, its interaction with adaptive client optimizers remains less understood. Adaptive optimizers such as Adam build each update from running averages of past gradients, so correcting only the final update direction leaves those averages, and the drift they contain, unchanged. We propose Federated Adaptive Gradient Correction ({\tt FA-GC}), which corrects each gradient before it enters these running averages, and compare it with Federated Adaptive Naive Tracking ({\tt FA-NT}), which adds the correction to the final direction. We show that, in an idealized setting without gradient noise, the direction FA-GC follows vanishes only at stationary points of the global objective, whereas the direction FA-NT follows can vanish elsewhere when the optimizer is nonlinear. We also prove convergence of FA-GC for Adam-family methods, gradient normalization, and Muon, which orthogonalizes matrix updates. Unlike our bound for FA-NT, these bounds contain no term for client heterogeneity. On seven image and language tasks, FA-GC with Adam needs the fewest rounds on average to reach the target accuracy, and on the three image tasks it also uses less total communication than uncorrected local Adam and FA-NT. On the QNLI question-entailment task with SOAP, which applies Adam in a rotated basis, and Muon under strong heterogeneity, FA-GC gives the highest accuracy, while FA-NT falls below the uncorrected optimizers.
2026-10-28 04:00:00 · AI应用,搜索RAG,联邦学习,招聘HR,论文
AI 资讯

Pricing Cross-Bank Context in Federated Anti-Money Laundering

arXiv cs.AIarXiv:2610.35996v1 Announce Type: cross Abstract: Most graph-based Anti-Money Laundering (AML) methods assume access to a pooled transaction graph containing all accounts and payments, which in reality does not exist. Federated learning offers the necessary privacy guarantees but it remains unclear how money laundering patterns spanning separate graphs can effectively be detected. We exploit transactions already recorded by both endpoint banks to approximate remote account states locally, enabling multi-layer Graph Neural Network (GNN) computation without additional account-specific exchange. Starting from this baseline, we test whether the remaining context is worth sharing, using a disclosure ladder that adds two transaction counts per remote account or the counterparty's own GNN states. On AMLworld HI-Small, across six GNN backbones and up to 32 silos, the observable baseline yields the largest gain and keeps it as fragmentation shrinks the visible slice; counts add a robust correction, while exact remote states help only in specific regimes. In controlled privacy--utility studies, the noise needed to protect shared states erases their detection value before it buys meaningful privacy, whereas counts stay useful even under strong privacy protection. These findings support a practical rule for banks: use what they already record, and formally protect the little that must move.
2026-10-28 04:00:00 · AI应用,搜索RAG,扩散模型,强化学习,图神经网络,联邦学习,招聘HR,论文
AI 资讯

Projection-Based Federated Learning on Compact Submanifolds with Geometry-Independent Differential Privacy

arXiv stat.MLarXiv:2610.33712v1 Announce Type: new Abstract: Federated learning trains a shared model across clients without exchanging their data, yet the updates they transmit still leak information about individual records. Enforcing differential privacy is harder still when the model parameters lie on a Riemannian manifold. Existing methods rebuild the noise added for privacy in the geometry of each new iterate, aggregate through intrinsic maps that often lack a closed form, and prove convergence only in restricted regimes. We introduce DP-RFedProj, a record-level differentially private federated learning method for compact submanifolds that aggregates through closed-form projections and privatises gradients in a fixed ambient geometry. Each client may run any stochastic first-order optimiser, take several local steps, and participate only intermittently. An explicit record-level $f$-DP guarantee holds for the entire training transcript, independently of the manifold, the aggregation scheme and the local optimiser. We establish convergence of DP-RFedProj when each client runs Riemannian SGD locally and the server aggregates by projected averaging, and show that privacy enters the rate through a term scaling with the manifold's intrinsic dimension rather than the ambient one. Synthetic experiments on federated PCA over the Grassmann manifold corroborate these findings. On EEG motor-imagery classification with SPDNet, whose weights lie on the Stiefel manifold, the method outperforms a Euclidean baseline at every privacy budget considered. In both experimental settings, our accounting requires five to six times less noise than that of the closest prior method for the same budget, which translates into higher utility.
2026-10-27 04:00:00 · AI应用,搜索RAG,联邦学习,招聘HR,论文
AI 资讯

Federated Learning: Why Averaging Model Updates Works - and When It Fails

DEV.to

Most machine learning still assumes a convenient fiction: all the data sits in one place, ready to be shuffled, split, and trained on. Real data rarely cooperates. It lives on phones, in hospitals, in banks, and in factories, where moving it is expensive, slow, or simply not allowed. Federated learning is the attempt to train anyway, without centralising the data.

The core idea is disarmingly simple. Instead of sending data to the model, send the model to the data. Each client trains locally, sends back only an update, and a server averages those updates into a new global model. That averaging step, called Federated Averaging or FedAvg, looks almost too naive to work. Understanding why it usually does work, and exactly where it breaks, is the key to using it well.

The problem FedAvg solves

Suppose there are K clients. Client k holds n_k examples, and n is the total number of examples across all clients. The global objective is a weighted average of local objectives:

F(w)=k=1∑K​nnk​​Fk​(w)

Here w is the model, and Fk​(w) is the loss on client k's data alone. The server never sees the data behind Fk​ . It only sees updates derived from it.

In a centralised setting, stochastic gradient descent would repeatedly compute a gradient on a random batch drawn from the whole population. In federated learning, each client can only draw batches from its own slice. If every client held a representative sample of the whole population, this would barely matter. In practice, clients are heterogeneous: one hospital sees different patients from another, one phone user types different words from the next, and one sensor sees a different operating regime. That heterogeneity, usually called non-IID data, is the central difficulty of the field.

FedAvg in one round

A round of FedAvg proceeds as follows:

  1. The server sends the current global model wt​ to a subset of clients.
  2. Each selected client runs several steps of SGD on its own data, starting from wt​ , and obtains a local model wtk
2026-10-27 05:03:33 · AI应用,搜索RAG,强化学习,联邦学习
AI 资讯

When Human Corrections Travel: Safety in Federated VLA Adaptation

arXiv cs.LGarXiv:2610.32888v1 Announce Type: cross Abstract: Vision-language-action (VLA) policies can adapt to local human intervention, while federated learning can combine distributed robot experience without pooling raw records. We examine their prospective intersection: sharing adaptations derived from diverse human corrections across tasks, environments, people, and robot embodiments. Corrections differ in modality, safety semantics(urgency, behavioral scope, etc.), and privacy sensitivity. A shared update that improves mean task success may suppress a rare safety intervention or produce an unsafe response on another robot. We argue for three requirements: preserve the context and uncertainty of multimodal corrections when deciding what to share; assess candidate updates in each receiving robot's closed loop before deployment; and evaluate leakage alongside retention of safety-critical evidence. Immediate, legible defensive behavior remains necessary during human interaction. We offer counterexamples and a falsifiable evaluation agenda, not experimental results.
2026-10-26 04:00:00 · 具身智能,多模态,联邦学习,招聘HR,论文
AI 资讯

Democratizing LLM Training with the Edge: Challenges, Systems, and the Road Ahead

arXiv cs.LGarXiv:2610.32215v1 Announce Type: cross Abstract: The growing computational power of modern GPU data centers has let a few industrial giants train and deploy large language models (LLMs) on massive amounts of data. Yet the sheer scale of these models and their training data makes centralized development increasingly hard to sustain, and at the same time shuts out smaller institutions that hold relevant private data but lack comparable infrastructure. In this paper, we organize our positions on distributed LLM training around the pretraining and fine-tuning paradigms, covering federated learning, split learning, and decentralized approaches, and we assess their readiness for geo-distributed settings with heterogeneous hardware and unreliable connectivity. We then present a {\em unified} system architecture built around a cloud-hosted parameter server that coordinates heterogeneous clients over outbound gRPC connections, reusing one communication, compression, and fault-tolerance stack for both pretraining and a family of fine-tuning methods. We validate the design with real geo-distributed experiments on GPT-2 Medium and Llama3-1B pretraining across multiple university sites, showing stable convergence under realistic conditions. Finally, we chart the road ahead, identifying open problems that span frontier model support, elastic fault tolerance, adaptive compression, federated alignment, privacy and trust, incentive design, and system--algorithm co-design, all of which must be addressed to make democratized LLM training a reality.
2026-10-26 04:00:00 · 大模型,算力芯片,OpenAI,Meta,扩散模型,强化学习,微调蒸馏,预训练,模型安全对齐,联邦学习,论文
AI 资讯

Clean-label Poisoning Attack and Defense Game for Federated Learning in Vehicular Networks

arXiv cs.AIarXiv:2610.32765v1 Announce Type: cross Abstract: This paper studies interactions between clean-label poisoning attack and defense in vehicular networks using federated learning (FL). Basic Safety Message (BSM) classification for anomaly detection is modeled as a distributed learning problem over a vehicular network with dynamic topology. As a critical threat to FL, a feature-space clean-label attack is introduced, wherein benign samples are perturbed toward malicious feature extremes, degrading class separability while preserving labels. To counter this, a feature-consistency relabeling defense is proposed to detect and relabel suspicious samples. A game-theoretic framework is developed to capture attack-defense interactions and characterize equilibrium strategies based on attack effectiveness and cost parameters. Results show that the attack scales effectively with compromised nodes, while the proposed defense keeps attack success low without degrading clean accuracy and shifts equilibrium regions toward attack-averse regimes.
2026-10-26 04:00:00 · 算力芯片,联邦学习,招聘HR,榜单评测,论文
AI 资讯

Multi-center Medical Data Mining with FL-Net - A One-stop Shop for Federated Learning

arXiv cs.LGarXiv:2609.20650v2 Announce Type: replace Abstract: Federated learning enables collaborative training without sharing patient-level data, but most studies remain simulations. Based on five requirements derived from the literature, we analyzed 14 FL frameworks and found that none fully satisfied these requirements. We present FL-Net, a novel federated clinical research framework to fulfill all requirements. It integrates modular data harmonization, data discovery, disclosure control, securely built versioned FL-Net-Tools and containerized federated workflow execution into a persistent network. It enables the re-use of harmonized data and workflows across studies. FL-Net's end-to-end capabilities were evaluated through harmonization, cross-study patient discovery across MIMIC and US-130, and reproducible, audited federated workflows with up to 50 concurrent clients. FL-Net is being developed within the dAIbetes and Microb-AI-ome EU projects and will cover over 800,000 patients across 10 hospitals in 9 countries covering longitudinal and single point in time data, FL-Net provides a practical foundation for interoperable, reproducible, and privacy-preserving multicenter clinical research.
2026-10-23 04:00:00 · 扩散模型,联邦学习,招聘HR,榜单评测,论文
AI 资讯

Evolving Federated Density Peak Clustering with Shuffler-Based Anonymization

arXiv cs.LGarXiv:2610.31211v1 Announce Type: new Abstract: In this paper, we present a novel one-shot federated clustering approach based on evolving fuzzy clustering and shuffler-based anonymization. In federated clustering, each round reveals additional model information to the server and can increase the opportunity to infer properties of local datasets, even when raw samples are never shared. Consequently, fewer client-server exchanges and unlinkability are important, so transmitted information cannot be attributed to any single client. Data-stream clustering algorithms, which learn in a single pass over the data, align well with the one-shot federated learning paradigm, where a single communication round can be sufficient. The proposed Evolving Federated Density Peak Clustering (eFDPC) method combines evolving fuzzy data-stream clustering and density peak clustering in a federated setting. Each client independently evolves micro-clusters from private data mini-batches through cluster addition and merging. To limit communication, density peak clustering is applied to the learned micro-clusters and only the selected peaks are transmitted, rather than the full local models. A shuffler-based layer is introduced between the clients and the server to anonymize contributions prior to reconstruction and global peak selection. We consider a peak-only variant, eFDPC-P, as well as eFDPC-G with server-side label propagation. Experiments on synthetic and real-world benchmark datasets show that eFDPC outperforms recent federated clustering baselines in one-shot settings and scales to higher-dimensional, non-IID data.
2026-10-23 04:00:00 · 扩散模型,强化学习,模型评测,联邦学习,招聘HR,论文
AI 资讯

Is High Local Accuracy Enough? Geometric Consensus with Support-Adaptive Statistical Personalization for Federated Learning

arXiv cs.LGarXiv:2610.31133v1 Announce Type: new Abstract: Real-world deployment of personalized federated learning (PFL) requires adapting to heterogeneous clients while preserving recognition performance beyond local distributions. However, high local accuracy can conceal failures on locally rare or absent classes. Effective personalization should therefore strengthen global recognition while raising the personalization floor. We propose an evaluation protocol that complements local accuracy with global, rare-class, and unseen-class evaluations to reveal generalization obscured by local scores, and assesses personalization floors among the worst-performing clients to expose weaknesses hidden by aggregate performance. To meet these deployment challenges, we propose FedGRC, a unified PFL framework integrating generalization and personalization through (i) Consensus-Guided Representation Learning (CGRL), which learns discriminative representations through shared directional and magnitude guidance; (ii) Multilayer Metric Synthesis (MMS), which constructs a shared covariance metric from these multilayer representations for statistical classification; and (iii) Support-Adaptive Shrinkage Personalization (SASP), which adapts class means within this metric by shrinking local estimates toward shared means according to local sample support, enabling adaptation while retaining shared knowledge. Extensive experiments, including benchmarking against 21 methods across 5 heterogeneity settings on 3 datasets and comprehensive ablation studies, validate the effectiveness of FedGRC. On CIFAR-10 and CIFAR-100, FedGRC surpasses state-of-the-art (SOTA) baselines in global recognition and personalization floors by at least 2.17% and 2.13%, respectively. On the real-world heterogeneous FedRS dataset, it outperforms the respective best baselines by 2.15%, 3.30%, and 4.61% in local adaptation, global recognition, and the personalization floor.
2026-10-23 04:00:00 · 强化学习,模型评测,联邦学习,招聘HR,论文
AI 资讯

FedBST: Bilateral Self-Training for Unsupervised Federated Classification
arXiv cs.CVarXiv:2610.30634v1 Announce Type: new Abstract: Unsupervised federated learning with Vision-Language Models (e.g., CLIP) offers a promising solution for label-free classification, yet its performance often degrades under severe non-IID shifts. A pioneering method, FedCoPL, typically relies on self-training strategies that exclusively prioritize high-confidence predictions for pseudo-labeling. However, this selective approach neglects the information of ambiguous samples (often referred to as ``waist" samples), leading to the underutilization of data and biased decision boundaries. To address this limitation, we propose FedBST, a bilateral self-training framework that effectively exploits both high-confidence and ambiguous data. Specifically, for local optimization, we introduce uncertainty-aware confidence penalization (UACP). UACP targets ambiguous samples by penalizing overconfident predictions to implicitly promote higher uncertainty, thereby preventing erroneous pseudo-labeling. At inference, we employ a visual-text ensemble strategy. This approach aggregates uncertainty-aware local visual prototypes and ensembles them with textual prototypes, achieving lightweight adaptation to local distributions via prototype-based calibration. Experiments demonstrate that FedBST achieves consistent improvements over existing methods with standard federated aggregation protocols.
2026-10-23 04:00:00 · 联邦学习,论文

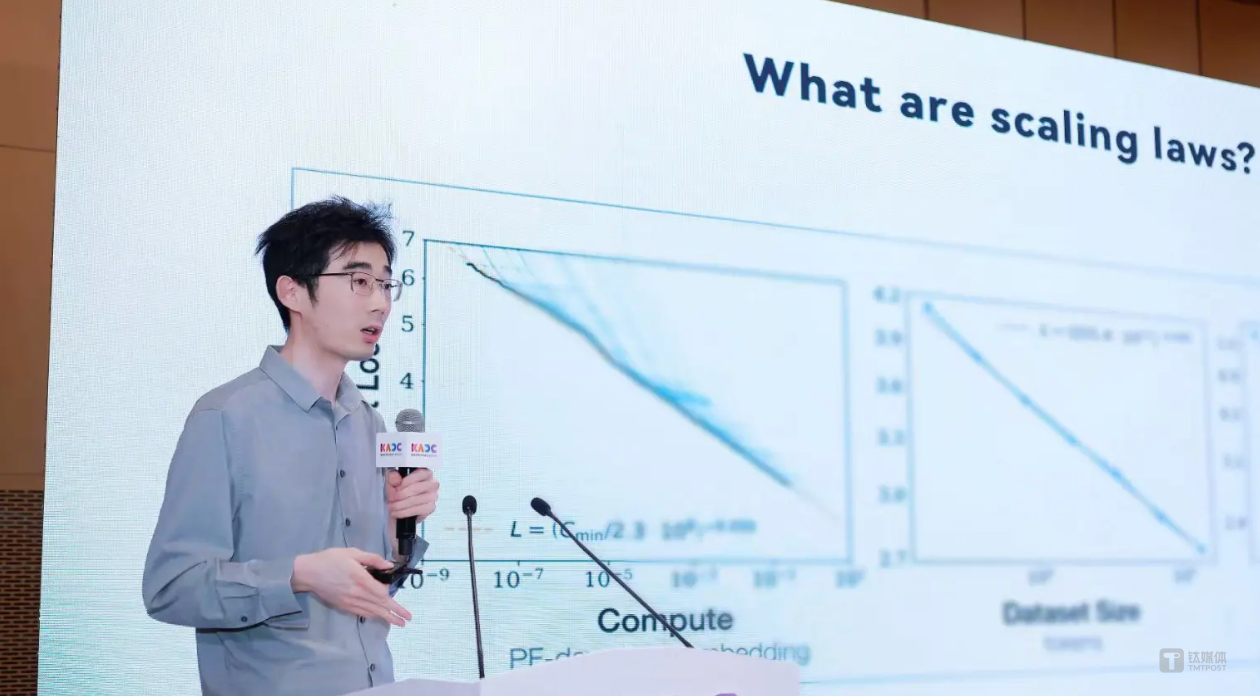
前千寻具身智能负责人解浚源北美创业,成立具身数采公司 gi labs

钛媒体

解浚源

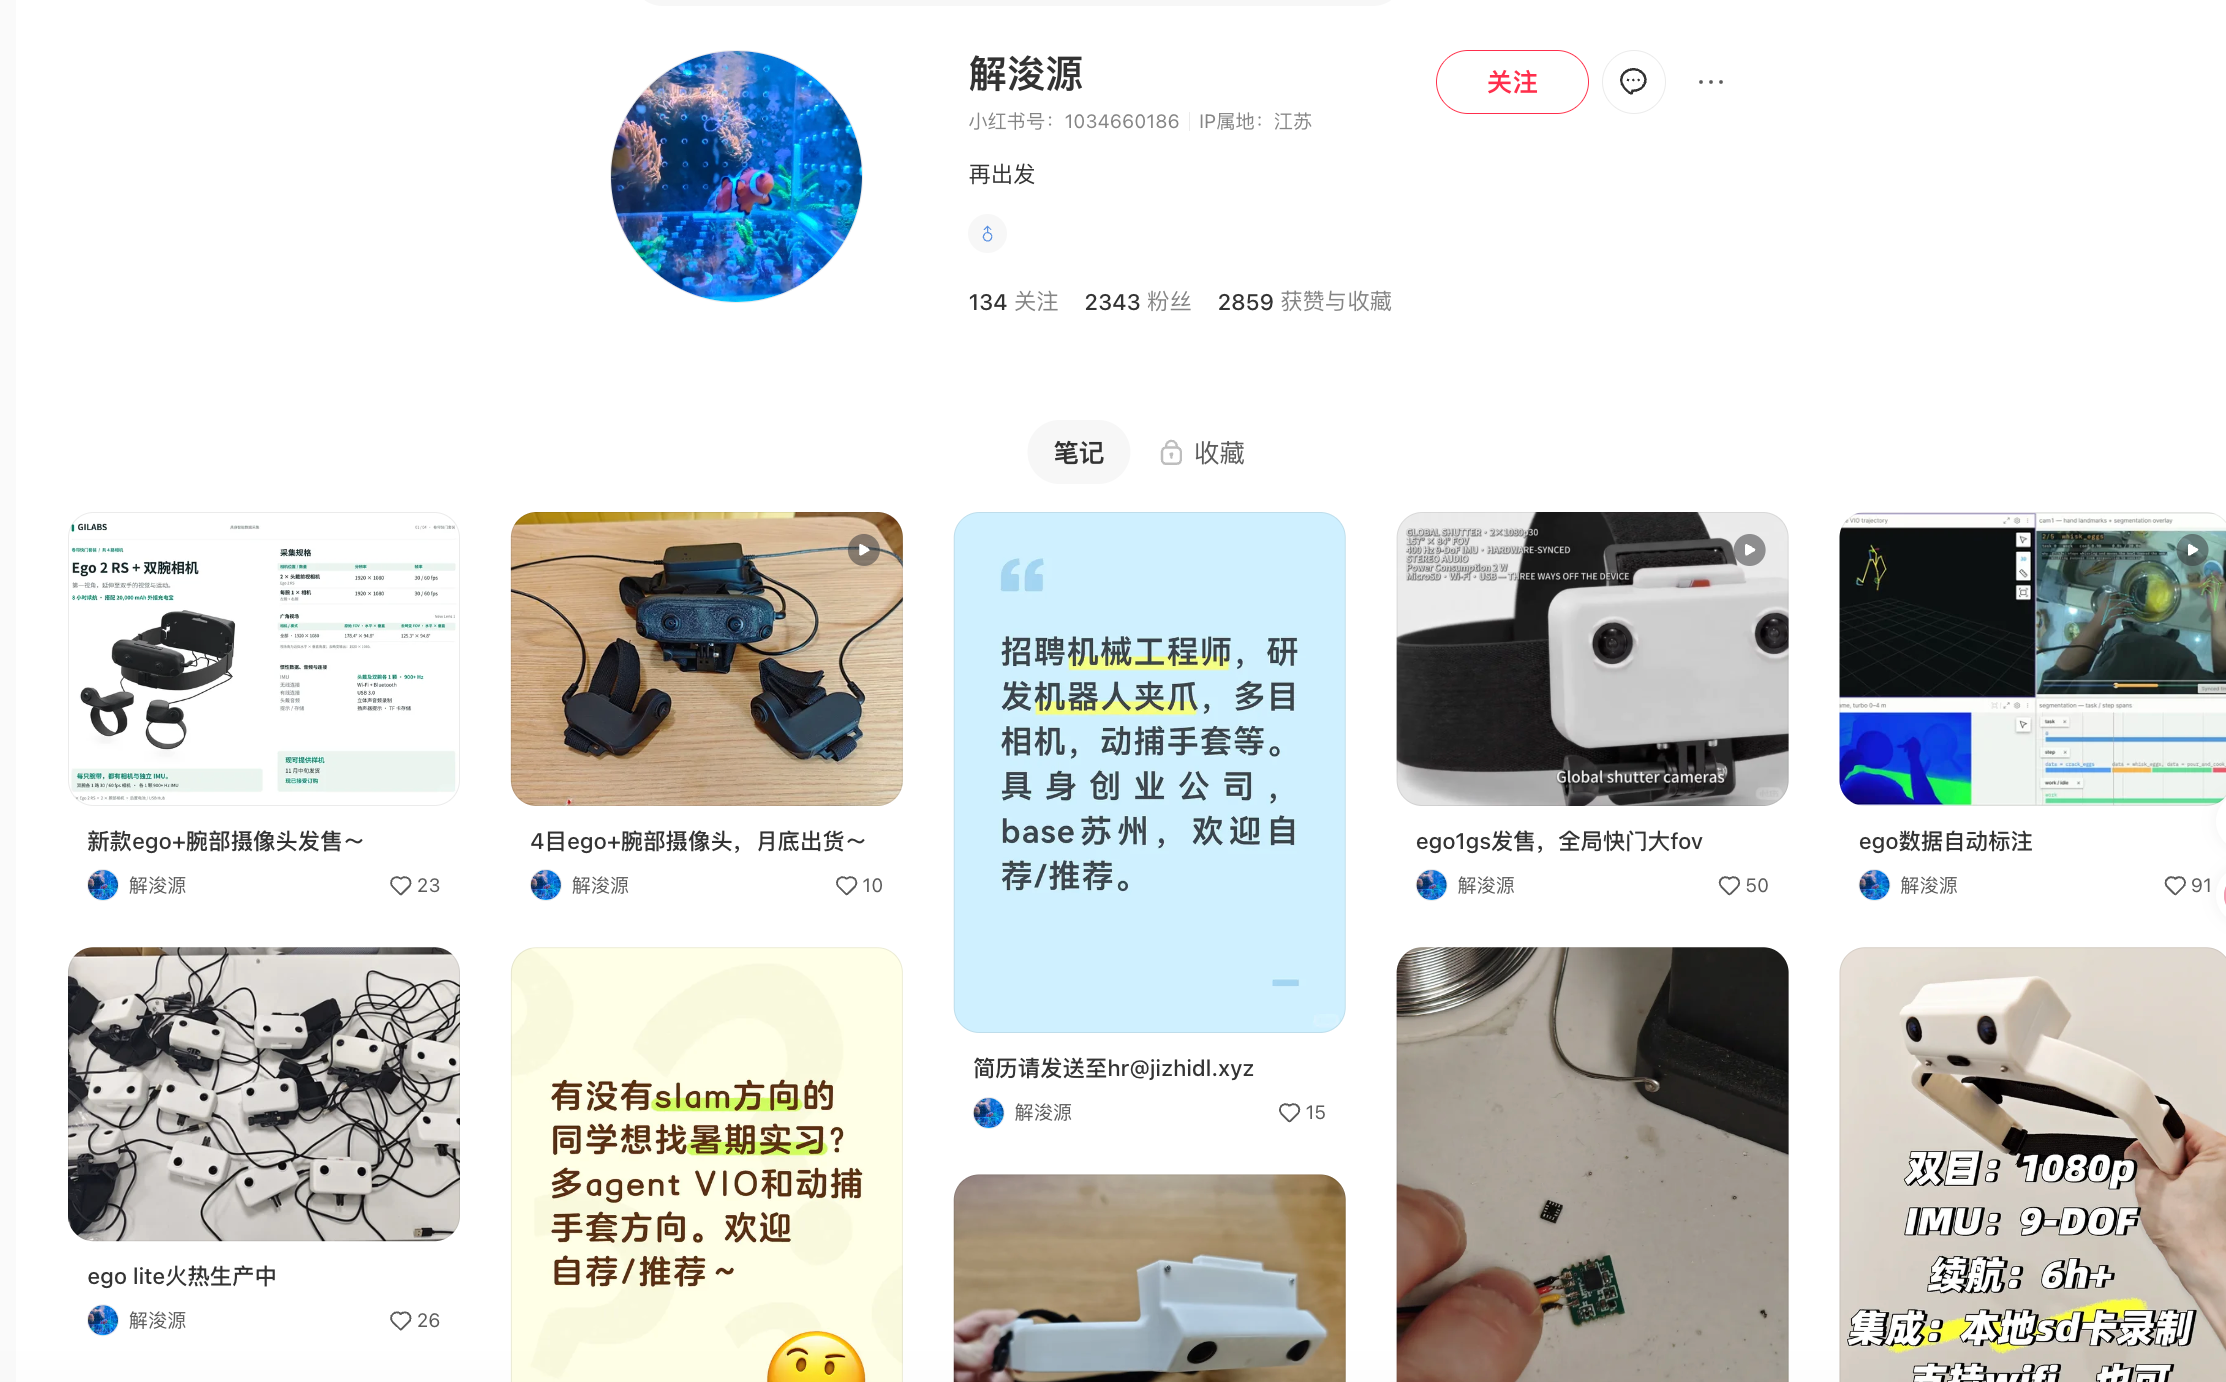
据悉,前千寻具身智能部负责人解浚源已在北美创业,成立gi labs(通用智能实验室),公司主要聚焦于打造数采设备,包括动捕手套、多目相机、机器人夹爪等。其中EGO1GS这款一体化数采头显搭载了1080p双目相机视场角可达157H 84D,并且采样频率达到前代的两倍,约400Hz。

据前述知情人士透露,gi labs目前在美国旧金山设立国外办公室,国内办公主要在苏州,团队由人工智能研究员、机器人学家和工程师组成。公司当前正在招聘机械工程师,并研发机器人夹爪、多目相机、动捕手套等产品。

产品层面,gi labs目前正在打磨新一代数据采集设备。知情人士称,该产品仍处于样机阶段,预计11月初陆续量产;定价单套3555元起,1000套以上为3150元/套。与上一代相比,新品核心区别在于帧率提升至60fps,视场角(FOV)也有所提升。
公开资料显示,解浚源本科毕业于中国科学技术大学,大三时以第一作者身份在NeurIPS发表图像去噪与修复论文,引用量超1900次。此后赴美国华盛顿大学攻读博士学位。其职业生涯涵盖亚马逊、字节跳动及千寻智能,曾主导MXNet系统研发,负责字节推荐系统与联邦学习平台,并在2025年至2026年期间全面负责千寻智能Spirit VLA大模型的推进,推动其在宁德时代、京东等场景落地。2026年2月,千寻智能完成两轮融资,总额近20亿元,估值突破百亿,投资方包括红杉中国、云锋基金、混沌投资及宁德时代等产业资本。解浚源此前曾持有其控股子公司万境千寻15%股份,已于今年3月退出,2026年4月,他正式从千寻离职。

当前具身数据的供需缺口也较大。中国信通院测算,具身模型要实现Chatgpt一样的突破,至少要有千万小时级有效数据支撑,而当前全球可用的高质量数据仅百万级。

但是,对解浚源和 gi labs 而言,履历与资本只是入场券,11 月量产交付与首批客户复购,才会给出第一笔硬答案。

更多精彩内容,关注钛媒体微信号(ID:taimeiti),或者下载钛媒体App

2026-10-23 03:58:50 · 大模型,具身智能,融资,OpenAI,字节跳动,京东,推理思考,办公效率,金融,教育学习,扩散模型,联邦学习,招聘HR,论文
AI 资讯

SeFoRA: Sketch-Aggregated Federated Low-Rank Adaptation with Heterogeneous Client Ranks

arXiv cs.LGarXiv:2608.10144v2 Announce Type: replace Abstract: We consider federated parameter-efficient fine-tuning of foundation models, e.g., LLMs and LVMs, using low-rank adaptation (LoRA; ~Hu et al.\ 2022). Combining LoRA with federated learning introduces challenges absent from either setting alone: clients may use different LoRA ranks, making their factor matrices dimension-incompatible, and factor-wise averaging suffers from a bilinear mismatch. We propose SeFoRA, a sketch-aggregated federated LoRA algorithm in which each client transmits a linear sketch of its local $\Delta \mathbf{W}$ updates, enabling direct aggregation at the federator. As a result, SeFoRA overcomes the rank heterogeneity challenge and alleviates the bilinear mismatch. We establish convergence to a neighborhood of a first-order stationary point at rate $\\mathcal{O}(T^{-1/2})$. Extensive numerical experiments on language and vision models showcase the performance of our algorithm compared to existing methods.
2026-10-22 04:00:00 · 大模型,AI应用,搜索RAG,微调蒸馏,联邦学习,论文
继续滚动加载更多…